Introduction
In our previous lesson, you successfully deployed and benchmarked a Llama 3 8B model using vLLM, observing firsthand how its PagedAttention and continuous batching mechanisms deliver high throughput by maximizing GPU utilization. This provided a crucial baseline for production performance.
Today, we continue our evaluation of top-tier inference frameworks by turning our attention to SGLang. While vLLM is renowned for raw throughput, SGLang offers a different, yet equally compelling, value proposition focused on performance and programmability.
Your goal for this lesson is to deploy the same model using SGLang and benchmark its baseline performance against vLLM. This direct, hands-on comparison will build your mental model of the inference landscape and start to form the basis for a key engineering skill: choosing the right tool for the job.
What is SGLang?
SGLang (Structured Generation Language) is another high-performance serving engine developed by researchers at LMSYS. Like vLLM, it is built on principles of continuous batching and efficient memory management to achieve high throughput. However, its name hints at its core differentiator: a focus on making complex, structured generation tasks both easy to program and highly performant.
To get a quick overview from the developers, watch the first couple of minutes of this talk.
Introduction to LLM serving with SGLang - Philip Kiely and Yineng Zhang, Baseten
The video 'Introduction to LLM serving with SGLang' provides a concise overview of the framework's goals and positioning.
Watch the segment from 02:01 to 03:13. The speakers introduce SGLang and place it in the context of other frameworks like vLLM.
While we will focus on baseline performance today, it's important to understand SGLang's dual focus. Under the hood, it employs optimizations similar to vLLM's PagedAttention (in SGLang, it's called RadixAttention) to manage the KV cache efficiently. This means for simple generation tasks, it is a direct competitor to vLLM on speed. We will put this to the test shortly.
The key architectural difference lies in its front-end language and runtime, designed to compile complex generation logic (e.g., control flow, multiple model calls, structured decoding) into an efficient execution plan for the backend.
Hands-On: Deploying and Benchmarking with SGLang
Let's move to the practical part. The process will feel familiar, as the ecosystem has largely standardized around OpenAI-compatible APIs and command-line interfaces. We'll use the same meta-llama/Llama-3-8B-Instruct model.
For a quick reference of the commands we'll be using, you can consult this cheat sheet. It conveniently places commands for vLLM and SGLang side-by-side.
LLM Benchmark - Python Cheat Sheet
The 'LLM Benchmark' cheat sheet is a handy reference for deploying and benchmarking various inference engines.
Briefly review the 'Quick Start' and 'Throughput' sections. Notice the similar structure of the commands for launching the server and running the benchmark for both vLLM and SGLang.
1. Install SGLang
SGLang provides different installation options depending on the backend. For compatibility with a wide range of GPUs, we will install it with the srt (SGLang Runtime) backend.
pip install "sglang[srt]"
2. Launch the SGLang Server
Now, launch the OpenAI-compatible server. SGLang's default port is 30000.
python -m sglang.launch_server --model-path meta-llama/Llama-3-8B-Instruct --port 30000
As before, if you haven't authenticated with Hugging Face, you may need to run huggingface-cli login. After the model is loaded, you will see Uvicorn start the server.
3. Run the Benchmark
With the server running, open a new terminal to run the benchmark. SGLang comes with a powerful benchmark script, bench_serving.py, that we can use to generate a load comparable to what we used for vLLM.
Run the following command:
python -m sglang.bench_serving \
    --backend sglang-oai-chat \
    --host localhost \
    --port 30000 \
    --model meta-llama/Llama-3-8B-Instruct \
    --dataset-name random \
    --random-input-len 512 \
    --random-output-len 512 \
    --num-prompts 500 \
    --request-rate inf \
    --max-concurrency 200
Notice how similar the parameters are to the vllm bench command. We are again simulating 200 concurrent users sending 500 total requests with 512 input and 512 output tokens. The --backend sglang-oai-chat flag tells the script to target the OpenAI-compatible chat completions endpoint.
While the benchmark runs, use nvidia-smi dmon -s um in another terminal to observe the GPU utilization. How does the pattern compare to what you saw with vLLM?
Analyzing the Results: SGLang vs. vLLM
Once the benchmark is complete, you will have a new set of performance metrics. Now is the time for the direct comparison.
-
Tabulate your results: Create a simple table in your notes comparing the key metrics from your vLLM benchmark in the last lesson and your SGLang benchmark today.
- Request throughput (req/s)
- Output token throughput (tok/s)
- Mean TTFT (ms)
- Mean ITL / TPOT (ms)
-
Watch an independent benchmark: It's useful to compare your findings with public, third-party benchmarks. The following video does exactly this, comparing vLLM and SGLang on a Llama 3.1 8B model.
How to pick a GPU and Inference Engine?
The video 'How to pick a GPU and Inference Engine?' provides a direct, data-driven comparison of several popular frameworks.
Watch the segments from 36:02 to 39:00, and the summary from 42:19 to 43:43. The presenter benchmarks SGLang and then vLLM using a similar methodology, and finally presents a summary graph comparing their throughput on single and concurrent requests.
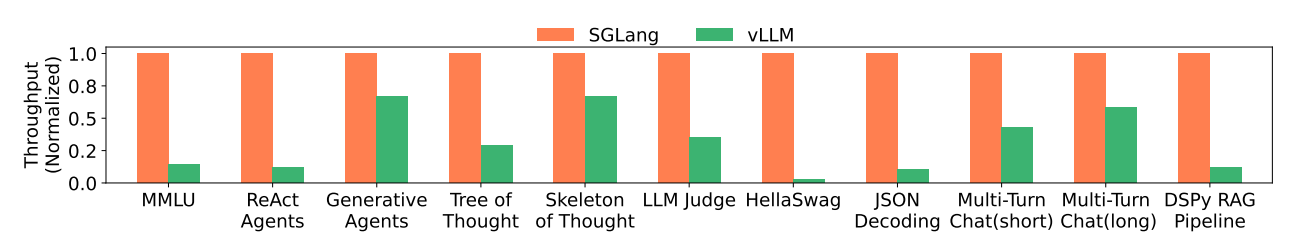
As the video demonstrates, and as your own results likely confirm, SGLang is highly competitive and often outperforms vLLM in terms of raw throughput, especially as concurrency increases.
The charts below, from a blog post by one of SGLang's authors, further illustrate this trend.

Why the Performance Difference?
You might be wondering: if both frameworks use similar core ideas (continuous batching, paged KV cache), why the performance delta?
- Implementation Details: The efficiency of CUDA kernels, the specific logic of the request scheduler, and the overhead of the Python server code all contribute. SGLang's
RadixAttentionmay have a more optimized kernel implementation or its scheduler might be more effective at packing requests into batches for certain workloads. - Design Philosophy: The final video clip from the SGLang introduction talk provides insight into its philosophy. It's not just about being fast, but also about being extensible.
Introduction to LLM serving with SGLang - Philip Kiely and Yineng Zhang, Baseten
To understand the motivation behind SGLang's design, listen to this answer about why a team might choose it.
Watch from 36:47 to 37:57. The speaker emphasizes configurability and the ability to contribute and unblock yourself as key advantages.
This points to a key takeaway for a systems engineer:
- vLLM is an exceptionally robust, well-supported, and highly performant engine, making it a default choice for high-throughput serving of standard generation tasks.
- SGLang offers potentially higher performance and, crucially, a more flexible and programmable front-end. This extensibility can be a decisive factor when your application requires complex, multi-step generative logic.
Conclusion
In this lesson, you have expanded your practical knowledge of the LLM serving landscape by deploying and benchmarking SGLang. By comparing its performance directly against vLLM, you've taken another step towards making informed, data-driven decisions as an AI Systems Engineer.
Key Takeaways:
- SGLang is a top-tier performer: For baseline text generation, SGLang is highly competitive with, and often faster than, vLLM in terms of throughput and latency.
- The ecosystem is standardizing: Deploying and benchmarking different frameworks involves very similar steps, tools, and metrics, simplifying the evaluation process.
- Performance is nuanced: While both frameworks share core architectural principles, specific implementation choices in their schedulers and CUDA kernels lead to measurable performance differences.
- Baseline speed isn't the whole story: SGLang's primary differentiator is its "Structured Generation Language," designed for performance on complex, programmable generation tasks.
Preview of the Next Lesson:
So far, we've only tested simple, open-ended generation. But many real-world applications require models to produce specific, structured outputs, such as JSON. In the next lesson, we will compare the structured generation capabilities of SGLang vs. vLLM, moving beyond baseline performance to evaluate the feature that gives SGLang its name and its unique power.