Introduction
In our last lesson, you benchmarked vLLM and SGLang for baseline, open-ended text generation. You saw that while both frameworks leverage similar core principles like continuous batching, SGLang often exhibits a performance edge, particularly as concurrency increases. This established SGLang as a strong contender for high-throughput serving.
Today, we dive into the feature that gives SGLang its name and its primary strategic advantage: structured generation. Many production AI systems require outputs that are not just free-form text but are formatted in a specific, machine-readable way, like JSON. Your goal in this lesson is to compare the structured generation capabilities of SGLang and vLLM, moving beyond raw throughput to evaluate their APIs, underlying mechanisms, and performance trade-offs for this critical task.
The Challenge of Structured Output
LLMs are fundamentally probabilistic models that generate a sequence of tokens. This is perfect for creative writing but problematic for applications requiring predictable, valid outputs for tool use, API calls, or database interactions. A model asked for JSON might return a malformed string, add conversational filler, or fail entirely, causing downstream systems to break.
The solution is guided decoding (also called constrained or structured generation). Instead of letting the model choose from its entire vocabulary at each step, we apply a set of rules—a grammar—to filter the model's output logits, forcing it to only select tokens that are valid according to the desired structure.
Let's explore how this works.
Guided Decoding Performance on vLLM and SGLang
To understand the fundamentals of guided decoding, we'll start with the article 'Guided Decoding Performance on vLLM and SGLang' from SqueezeBits.
Read the 'Introduction' and 'How Guided Decoding Works' sections. Focus on the three-step process: creating a grammar, generating a token mask, and applying the mask to the logits. This provides the conceptual foundation for everything that follows.
At its core, guided decoding compiles a schema (e.g., a JSON schema or a regular expression) into a Finite State Machine (FSM). At each step of generation, the FSM, based on the tokens already generated, determines the set of all possible valid next tokens. This set is converted into a bitmask that is applied to the model's logits, effectively zeroing out the probabilities of all invalid tokens.
Given your background, you might find this visualization of the underlying data structures and process insightful. It depicts the grammar as a Pushdown Automata (a more powerful FSM) and illustrates how it's used to generate token masks.

Frameworks, Backends, and System-Level Bottlenecks
Implementing guided decoding efficiently is a non-trivial systems problem. The process of generating the token mask at every step is CPU-intensive, while the LLM forward pass is GPU-intensive. A naive, sequential implementation can lead to the CPU becoming a major bottleneck, leaving the expensive GPU idle.
The performance of structured generation depends on two main factors:
- The Grammar Backend: The library responsible for parsing the schema and generating masks.
- The Serving Framework: The engine (vLLM or SGLang) that integrates the grammar backend and orchestrates the CPU and GPU work.
1. Grammar Backends: xGrammar vs. LLGuidance
There are two dominant open-source grammar backends. Their differing strategies have significant performance implications.
Guided Decoding Performance on vLLM and SGLang
The SqueezeBits article provides an excellent comparison of the two main grammar backends.
Read the sections 'XGrammar' and 'LLGuidance'. Pay close attention to the strategic difference: xGrammar focuses on pre-computation and caching, while LLGuidance uses a more dynamic, on-the-fly approach.
To summarize:
xGrammaris optimized for repetitive, simple schemas. It does a lot of work upfront to pre-compute and cache masks, making subsequent generation very fast if the schema is reused.LLGuidanceis better for dynamic or complex schemas. Its lazy, on-the-fly approach has lower initialization overhead, making it more robust when every request might have a unique schema.
2. Serving Framework Integration
Even with an efficient grammar backend, performance hinges on how the serving framework integrates it. This is where SGLang's architecture creates a distinct advantage.
Guided Decoding Performance on vLLM and SGLang
This is the key systems-level insight. Let's return to the SqueezeBits article to see how framework design impacts performance.
Read 'The Decisive Factor: Serving Framework Integration' and study Figure 3. Note how SGLang's design allows it to overlap the CPU-bound mask generation with the GPU-bound LLM inference, effectively hiding the overhead.
This CPU/GPU overlap is a core reason for SGLang's superior performance in structured generation tasks. By treating the grammar engine as a coprocessor, it minimizes GPU idle time and overcomes the CPU bottleneck that can plague other systems.
Hands-On: Comparing JSON Generation
Now, let's see this in action. We'll task both vLLM and SGLang with a simple structured generation task: extracting information from a sentence into a predefined JSON schema.
1. JSON Generation with vLLM
Recent versions of vLLM's OpenAI-compatible server support a "JSON mode" that forces the output to be valid JSON. It's a convenient feature, but as we'll see, it's a general constraint and doesn't enforce a specific schema. For more complex schema enforcement, you would typically integrate a library like outlines. For our comparison, we will use the built-in JSON mode.
First, ensure you have the latest compatible packages installed:
pip install vllm openai
Now, launch the vLLM server (if it's not already running):
python -m vllm.entrypoints.openai.api_server --model meta-llama/Llama-3-8B-Instruct
In a separate file (e.g., test_vllm_json.py), use the following script to send a request with JSON mode enabled.
import openai
import json


# Point to the local vLLM server
client = openai.OpenAI(
    base_url="http://localhost:8000/v1",
    api_key="vllm"
)


# Define the prompt and desired schema
prompt_text = "The user is Jane Doe, an engineer from New York. Her user ID is 12345."
json_schema = {
    "name": "string",
    "city": "string",
    "user_id": "integer"
}


# Use a system prompt to guide the model towards the schema
# Note: vLLM's json_mode does not enforce the schema, only that the output is valid JSON.
# We rely on the model's ability to follow instructions.
response = client.chat.completions.create(
    model="meta-llama/Llama-3-8B-Instruct",
    messages=[
        {"role": "system", "content": f"You are a helpful assistant that extracts information into a JSON object. The JSON object must conform to the following schema: {json.dumps(json_schema)}"},
        {"role": "user", "content": prompt_text}
    ],
    temperature=0.0,
    response_format={"type": "json_object"} # This enables JSON mode
)

output = response.choices[0].message.content
print("--- vLLM Output ---")
print(output)


# Verify correctness
try:
    json.loads(output)
    print("\n[SUCCESS] Output is valid JSON.")
except json.JSONDecodeError:
    print("\n[FAILURE] Output is not valid JSON.")
Run this script. You should see a valid JSON object printed. The key takeaway here is the API: it's an OpenAI-compatible flag, response_format, combined with prompt engineering.
2. JSON Generation with SGLang
SGLang provides a much more direct and powerful way to handle structured generation via its Python-native DSL (Domain-Specific Language) and json_schema argument.
First, ensure you have SGLang installed:
pip install "sglang[srt]"
Unlike the server-client model we just used for vLLM, we can use SGLang's library directly in a script. This highlights its different programming model. Create a file test_sglang_json.py:
import sglang as sgl
import json


# This automatically launches a backend runtime
sgl.set_default_backend(sgl.srt.Runtime(model_path="meta-llama/Llama-3-8B-Instruct"))


# Define the prompt and desired schema
prompt_text = "The user is Jane Doe, an engineer from New York. Her user ID is 12345."
json_schema = {
    "type": "object",
    "properties": {
        "name": {"type": "string"},
        "city": {"type": "string"},
        "user_id": {"type": "integer"}
    }
}


# Define the generation function using SGLang's DSL
@sgl.function
def extract_info(s, text):
    s += f"You are a helpful assistant that extracts information into a JSON object.\n"
    s += f"USER: {text}\n"
    s += f"ASSISTANT: "
    s += sgl.gen("json_output", max_tokens=128, json_schema=json.dumps(json_schema))


# Run the SGLang function
state = extract_info.run(text=prompt_text)
output = state["json_output"]

print("--- SGLang Output ---")
print(output)


# Verify correctness (SGLang's grammar guarantees this)
try:
    data = json.loads(output)
    print("\n[SUCCESS] Output is valid JSON.")


    # More advanced check: Does it fit the schema? (This requires a schema validator library)
    assert isinstance(data.get("name"), str)
    assert isinstance(data.get("city"), str)
    assert isinstance(data.get("user_id"), int)
    print("[SUCCESS] Output conforms to the expected types.")

except (json.JSONDecodeError, AssertionError) as e:
    print(f"\n[FAILURE] Output validation failed: {e}")
Run the script. Notice two key differences:
- Programming Model: You are writing a Python function that directly composes the prompt and generation steps. This is SGLang's DSL.
- Schema Enforcement: The
json_schemaargument directly integrates a grammar (likely xGrammar under the hood) to guarantee the output conforms to the schema, not just that it's valid JSON. This is a much stronger guarantee than vLLM's JSON mode.
Performance and Capability Analysis
Your hands-on test reveals the difference in developer experience and guarantees. Now let's look at the performance data.
The blog post "Inside SGLang" provides a direct benchmark for JSON generation that is highly illuminating.
Inside SGLang: Anatomy of a High-Performance Structured LLM ...
This resource provides head-to-head performance numbers for the exact task we are studying.
First, study the 'JSON Generation Benchmark' table in the 'Structured Generation Performance' section. Note the dramatic difference in tokens/sec and latency between 'vLLM + Guidance' and the SGLang options. Then, review the 'Comparison with vLLM' table and the 'When to Choose SGLang vs vLLM' section in the epilogue. These summarize the key trade-offs.
The data is unequivocal:
- Performance: For structured generation, SGLang is significantly faster, achieving much higher throughput and lower latency. The benchmark shows a >5x throughput advantage for SGLang over
vLLM + Guidance. - Validity: SGLang provides near-perfect validity rates by design.
- Capability: SGLang's DSL and deep grammar integration are purpose-built for these tasks, whereas for vLLM it is more of an add-on feature.
The throughput chart you saw in the last lesson further reinforces this point. The "JSON Decoding" task shows one of the most dramatic performance gaps between the two frameworks.
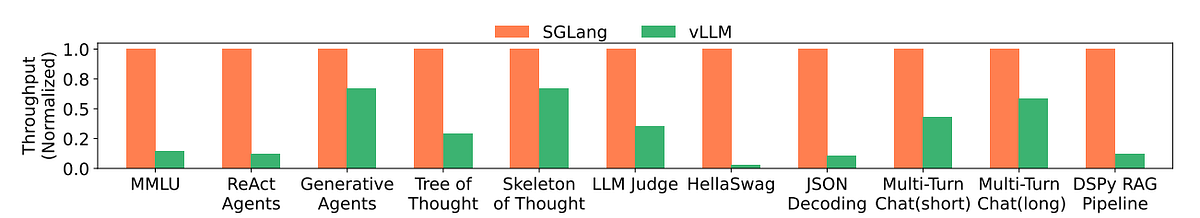
Finally, the SqueezeBits benchmarks offer the most detailed analysis, confirming that SGLang's architectural superiority in overlapping CPU/GPU tasks makes it the clear winner for most guided decoding scenarios.
Guided Decoding Performance on vLLM and SGLang
Let's conclude with the key findings from the SqueezeBits performance analysis.
Quickly scan the results in 'Performance on Repetitive Schemas' and 'Performance on Dynamic Schemas'. Then, read the 'Conclusion' carefully. It provides a clear decision framework for when to use which tool, confirming SGLang's advantage is due to its system architecture.
Conclusion
You have now moved beyond baseline benchmarks to compare vLLM and SGLang on a feature that is critical for building robust AI systems. While vLLM is an excellent engine for high-throughput, open-ended generation, SGLang's design gives it a decisive advantage when structured outputs are required.
Key Takeaways:
- Structured Generation is a Systems Problem: Efficiently guiding LLM output requires not just a grammar, but tight integration between the CPU-bound grammar engine and the GPU-bound inference kernel.
- SGLang's Architecture is Superior for this Task: By treating structured generation as a first-class citizen and designing its scheduler to overlap CPU and GPU work, SGLang largely eliminates the overhead of guided decoding.
- Developer Experience and Guarantees Differ: SGLang offers a powerful, Python-native DSL for composing complex generation flows and provides strong guarantees of schema conformance. vLLM's approach is simpler for basic JSON but less powerful and offers weaker guarantees without third-party libraries.
- The Right Tool for the Job: For simple, high-throughput text generation, vLLM remains a top choice. For applications requiring reliable, high-performance structured outputs (e.g., agentic workflows, API calling), SGLang is the clear technical leader.
Preview of the Next Lesson:
So far, we have evaluated frameworks that use JIT (Just-In-Time) compilation and interpretation. There is another major paradigm for optimizing inference: Ahead-Of-Time (AOT) compilation. In our next lesson, we will build and deploy a model using NVIDIA's TensorRT-LLM, which compiles a model into a highly optimized engine, and benchmark its performance against the frameworks we've already studied.