Hello! Welcome to the fourth module of our course, "Incrementality and True Marketing Impact."
In our last lesson, we focused on how to critique the design of common incrementality tests. We established that user-level holdouts (like Meta's Conversion Lift) are the gold standard for precision, while geo-lift tests are a powerful but more volatile alternative. Your key takeaway was that as a leader, you must question the test's setup—its randomization, matching, and control for biases—before you can trust its findings.
Now that we know what makes a good test, our focus shifts to making sense of its output. Today's learning outcome is to interpret the results of an incrementality test to determine a channel's causal impact. This isn't just about reading numbers; it's about translating statistical outputs into a clear, confident business decision. Does this channel deserve more budget, less, or a complete rethink? Let's find out how to answer that question.
1. From Correlation to Causation: The Core Output
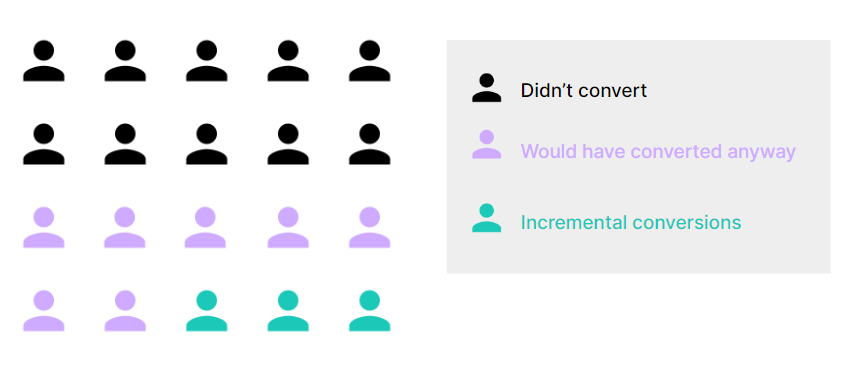
Before diving into complex charts, let's solidify the core concept. An incrementality test isolates causation. It tells you what happened only because of your ads, separating the signal from the noise of customers who would have converted anyway.
CORRELATION vs CAUSATION - DIFFERENCE for your FACEBOOK A/B Test & CONVERSION Lift tests
To grasp this distinction, let's watch a segment from the video 'CORRELATION vs CAUSATION' by Markeko. It uses a simple, powerful example to illustrate how a lift test isolates causal impact.
Please watch from 12:12 to 16:32. Pay close attention to the example of Michelle (test group) and Justine (control group). This clearly explains how comparing the two groups reveals the 'incremental lift'.
The video's example is the essence of what we're measuring. The 2% difference in purchase rate between the test and control groups is the incremental lift. This is the true, causal impact of your remarketing campaign.
Key Metrics to Interpret
When you receive the results of an incrementality test, you'll typically see a few key metrics. Let's define them using the clear formulas from "The Ultimate Guide to Incrementality Testing."
The Ultimate Guide to Incrementality Testing
This article from Impression Digital provides the precise definitions for the core metrics you'll be interpreting. We'll focus on the section that lays out the calculations.
Please read the section titled 'How to calculate incrementality and lift'. Focus on understanding the definitions of 'Lift' (which is the same as Causal Impact) and 'Incrementality'.
Based on that reading, here are the primary outputs you'll need to interpret:
-
Causal Impact (or Lift): This is the absolute number of additional outcomes (conversions, sales, sign-ups) that were caused by your campaign.
This is your bottom-line result. For example, "This campaign generated 850 incremental sales." -
Incrementality Percentage: This expresses the causal impact as a percentage of the total outcomes in the test group, showing how much of your success was truly incremental.
For example, "Of all the sales we saw in the test regions, 15% were incremental." -
Incremental ROAS (iROAS): This is the Return On Ad Spend calculated using only the incremental revenue.
This is the most critical metric for budget decisions. An iROAS of 3.0x means every dollar spent on the campaign generated three dollars in causal revenue. We will explore this metric in depth in our next lesson.
2. Visualizing and Interpreting a Test's Output
How are these results typically presented? The output can range from a simple summary to a detailed time-series chart. Let's look at a common and powerful visualization used for geo-lift tests.

For a more granular view, especially with geo-tests analyzed using models like Google's CausalImpact, you'll see a series of charts that tell a richer story.
Jessica Tyler: Geo Experiments and Causal Impact in Incrementality Testing | PyData New York 2019
The PyData talk by Jessica Tyler provides an excellent walkthrough of the standard Causal Impact visualization. Understanding these three plots is key to interpreting many modern incrementality tests.
Watch the segment from 17:29 to 19:08. The speaker explains the three charts that are standard output for a Causal Impact analysis. Focus on what each chart represents.
Let's break down those three charts from a business leader's perspective:
- Top Plot (Actual vs. Predicted): This shows what really happened (solid line) versus what the model predicted would have happened without your ads (dotted line). The shaded area between them is the confidence interval. The moment the solid line clearly separates from the dotted line is when your campaign started having a causal effect.
- Middle Plot (Pointwise Effect): This shows the incremental lift for each day of the campaign. It helps you see when the impact occurred. Did it start immediately? Did it grow over time? Was the impact consistent? This is useful for understanding campaign dynamics.
- Bottom Plot (Cumulative Effect): This is often the most important chart for a summary view. It shows the total, cumulative incremental lift over the entire test period. The final value on this chart is the total causal impact of your campaign.
When you see these charts, you should be able to answer: "Did we see a lift?", "How big was it?", and "Was it consistent throughout the campaign?"
3. "Are You Sure?" – Interpreting Confidence Levels
You'll never get a single number as a result. You'll get a number and a measure of confidence, typically a p-value or a confidence interval. This addresses the natural volatility in data. Your marketing intuition and experience are valuable, but this statistical rigor ensures you're not making decisions based on random noise.
The Ultimate Guide to Incrementality Testing
Let's return to 'The Ultimate Guide to Incrementality Testing' to understand how to interpret these statistical measures. This is the 'fine print' that determines if a result is real or a fluke.
Please read the section 'How to interpret the results of your incrementality test'. Focus on the distinction between Bayesian credible probabilities and frequentist p-values.
Here’s a simplified guide for interpreting these from a leadership perspective:
-
P-value (Frequentist): You'll see something like "p < 0.05".
- Interpretation: "The probability of seeing a lift this large purely by random chance is less than 5%."
- Your Action: A low p-value (typically under 0.05 or 0.10) gives you the confidence to act on the result. If p is high (e.g., 0.40), the result is likely noise, and you cannot conclude the campaign had a causal impact.
-
Confidence/Credible Interval (Bayesian): You'll see a range, like "Incremental Conversions: 1,200 [950, 1450]".
- Interpretation: "We are 95% confident that the true number of incremental conversions is somewhere between 950 and 1,450." This is generally more intuitive for business planning.
- Your Action: The most critical check is whether the interval includes zero.
- An interval like [950, 1,450] is great. It's statistically significant and positive.
- An interval like [-100, 400] is not statistically significant. Because it contains zero, you cannot be confident that the effect isn't just random. The true impact could be negative, zero, or positive. You cannot make a decision to scale based on this.
Test your understanding!
Your team presents the results of a geo-lift test for a YouTube campaign. The headline result is "+500 incremental sales".
The confidence interval is [-150, 1150] and the p-value is 0.13.
What is your interpretation, and what is your immediate decision?
Show answer
Interpretation: Although the average result was +500 sales, the result is not statistically significant. The confidence interval includes zero, meaning the true impact could plausibly be negative (-150 sales). The p-value of 0.13 is also higher than the typical threshold for significance (e.g., 0.05 or 0.10). You cannot confidently conclude that the YouTube campaign had any causal impact.
Immediate Decision: Do not scale the campaign based on this data. The next step is to investigate why the result was inconclusive. Was the test too short? Was the spend too low to create a detectable effect? Or is the channel simply not incremental?
4. From Interpretation to Action: A Strategic Framework
Interpreting the numbers is only half the battle. Your primary role is to translate that interpretation into a concrete action plan.
How to Analyze Marketing Data After an Incrementality Test
The article 'How to Analyze Marketing Data After an Incrementality Test' provides an excellent, decision-oriented framework for exactly this purpose. It moves beyond single metrics to a holistic action plan.
Please read 'Step 3: Translate the Data Into a Clear Action Plan', paying close attention to the scenarios for both positive and negative results. This is your playbook for turning insights into strategy.
Let's synthesize this into your strategic decision framework.
Scenario 1: The Results are Positive and Significant
The test shows a clear, statistically significant lift (e.g., iROAS of 3x, p < 0.05).
Incorrect Action: Immediately double the budget.
Correct Action Plan (as outlined in the article):
- Scale Incrementally: Increase the budget by a controlled amount (e.g., 10-20%).
- Isolate the Variable: Keep all other factors (creative, targeting) constant to ensure you're measuring the effect of the budget increase.
- Monitor Performance: Track overall metrics like Marketing Efficiency Ratio (MER) to see if the small-scale lift translates to a lift in total business efficiency.
- Plan the Next Test: Incrementality is a continuous process. The next test could be to see if this lift holds at an even higher spend level.
Scenario 2: The Results are Negative or Insignificant
The test shows no statistically significant lift (e.g., iROAS of 0.5x, or a confidence interval that includes zero).
Incorrect Action: Immediately kill the channel forever.
Correct Action Plan:
- First, Validate the Test: Revisit the lessons from our previous session. Was the test design sound? Was the duration long enough? Was the spend sufficient to create a detectable effect? A "no lift" result from a broken test is meaningless.
- Diagnose the "Why": If the test was valid, consider the potential causes.
- Creative: Is the creative failing to resonate?
- Targeting: Are we reaching the wrong audience?
- Strategy: Is this a top-of-funnel channel where the impact might be delayed or appear in other channels?
- Formulate a New Hypothesis: Based on your diagnosis, decide on the next step. It could be:
- De-prioritize & Reallocate: Shift budget to a channel with proven incrementality.
- Iterate & Re-test: Launch a new test with improved creative or different targeting.
Conclusion
Interpreting incrementality results is a core competency for a modern marketing leader. It empowers you to move beyond platform-reported vanity metrics and make budget decisions based on true, causal business impact.
Key Takeaways:
- Focus on Causality: Your goal is to isolate the lift caused only by your marketing, separating it from what would have happened anyway.
- Master the Core Metrics: You must be fluent in what Causal Impact, Incrementality %, and iROAS represent.
- Respect the Statistics: A result without statistical significance (p-value > 0.10 or a confidence interval containing zero) is not a reliable signal. You cannot confidently act on it.
- Translate Insights to Action: Every test result, whether positive or negative, should lead to a structured, strategic action plan—to scale intelligently, diagnose problems, or reallocate resources.
Preview of the Next Lesson:
We briefly touched on the most powerful metric for decision-making: Incremental ROAS (iROAS). In our next lesson, we will put it head-to-head with the platform-reported ROAS you see in your Google and Meta dashboards. Understanding the inevitable gap between these two numbers—and explaining it to stakeholders—is one of the most important strategic conversations you will lead.