
Hello. In the previous lesson, you separated TCP success from TLS success: a connection can complete at the network layer yet still fail during encryption or certificate validation. Now assume DNS, TCP, and—where applicable—TLS have reached a usable HTTP connection. The question becomes: which HTTP-speaking component produced, transformed, delayed, or failed to forward the request?
This lesson builds an evidence-led method for locating a failure across the client, a corporate forward proxy, an internet-facing load balancer, a reverse proxy or ingress layer, and the application. The objective is not to memorize that “502 means load balancer”; it is to make a narrow, defensible claim supported by request traces, timings, headers, and correlated logs.
Map the request path before diagnosing it
An HTTP request often passes through several independently configured components. The exact topology varies, and one product can perform more than one role, but the diagnostic boundaries are still useful:
| Boundary | Typical responsibility | Useful evidence |
|---|---|---|
| Client | Builds URL, headers, body, cookies, and authentication; chooses proxy settings | Browser network trace, application logs, curl -v, client-side timing |
| Forward proxy | Represents the client’s network; may authenticate, filter, inspect, or cache outbound traffic | Proxy configuration, 407 or policy response, proxy access logs |
| Load balancer / edge gateway | Accepts public traffic, terminates TLS, applies WAF or routing rules, chooses a healthy target | Access logs, listener/routing config, target health, edge-generated response headers |
| Reverse proxy / ingress | Routes by host, path, header, or cookie; may serve static content and proxy to upstreams | NGINX/Ingress access and error logs, upstream address/status/timing |
| Application | Authorizes, validates, executes business logic, calls dependencies, returns response | Application logs, traces, metrics, dependency errors |
A reverse proxy and load balancer are not mutually exclusive. A cloud load balancer may distribute traffic to an internal NGINX ingress layer, which then routes requests to application instances. That means a single browser error can have several plausible sources.
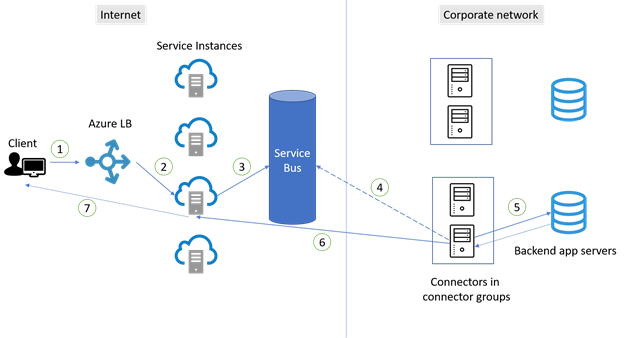
The key idea is simple:
An HTTP status code identifies what the client received, not necessarily which component originally caused the condition.
For example, a 502 Bad Gateway returned by an ingress proxy may reflect a refused connection to an application. But an application that is itself calling another service may generate its own 502. The same number can therefore occur at more than one layer.
To orient the architecture quickly, watch this focused overview. It distinguishes the client-side role of a forward proxy from the server-side role of a reverse proxy, then places cloud load balancers and internal reverse proxies in a realistic layered design.
Proxy vs Reverse Proxy vs Load Balancer | Simply Explained
Watch “Proxy vs Reverse Proxy vs Load Balancer | Simply Explained” by TechWorld with Nana to establish the traffic roles you will use as diagnostic boundaries.
Watch forward proxies for the client-network intermediary role. Then watch reverse proxies to distinguish an inbound reverse proxy from a forward proxy. Finish with layered routing, which explains why a cloud load balancer and an internal proxy often both appear in one production request path. Focus on what each layer can observe and change.
Create one reproducible client-side observation
Start with the smallest request that represents the user-visible failure. Ideally, use the same:
- hostname and path;
- HTTP method;
- authentication state or service identity;
- relevant headers;
- network location;
- request body, if it is essential and safe to reproduce.
Do not begin with curl -k, -L, or a browser refresh loop. Those options can hide the evidence you need:
-kdisables certificate validation, which invalidates part of the transport diagnosis.-Lfollows redirects, hiding the response that issued the redirect.- repeated refreshes can produce different load-balancer target selection, cache behavior, rate limiting, or log noise.
Use verbose mode first. It exposes DNS resolution, proxy use, connection establishment, TLS negotiation, the request line, headers, response headers, and HTTP status.
url='https://api.example.internal/v1/orders/123'
request_id="$(uuidgen)"

curl --silent --show-error --verbose --trace-time \
  --connect-timeout 3 \
  --max-time 15 \
  -H "X-Request-ID: ${request_id}" \
  -D "/tmp/response-headers.${request_id}" \
  -o /dev/null \
  -w $'\nhttp=%{http_code} remote=%{remote_ip}:%{remote_port} dns=%{time_namelookup}s connect=%{time_connect}s tls=%{time_appconnect}s first_byte=%{time_starttransfer}s total=%{time_total}s\n' \
  "$url"
Treat the output as a timeline, not as a block of noise:
- Proxy selection: Does curl say it is using
HTTPS_PROXY,HTTP_PROXY, orALL_PROXY? For HTTPS through a conventional forward proxy, look for aCONNECTrequest. - Remote IP and port: Which endpoint did the client actually contact? It may be a proxy IP rather than the public load balancer.
- TLS boundary: Did TLS finish successfully? This was the focus of the previous lesson.
- Request: Confirm the
Hostheader, path, method, and relevant request headers are what you expected. - Response: Record status, response headers, response body signature if safe, and timings.
The timing fields are cumulative:
dnscovers name lookup.connectcovers reaching the TCP-connected state.tlscovers establishing TLS when HTTPS is used.first_byteis the time until the first response byte arrives.totalis the time until the response body is fully received.
So if tls is fast but first_byte is close to the timeout, the delay is likely after the secure connection was established: perhaps queueing, proxy-to-upstream connection, application processing, or an application dependency. That is a hypothesis, not yet a conclusion.
Use a unique correlation ID only if your platform is designed to accept and propagate it. Many proxies generate or replace request IDs, so record both your client-generated value and any returned ID such as X-Request-ID, X-Amzn-Trace-Id, or a vendor-specific request identifier. Never put tokens, cookies, customer data, or secrets into a request ID.
Curl’s own documentation is a good compact reference for this evidence-gathering workflow.
The Art Of Scripting HTTP Requests Using Curl
Read curl’s “The Art of Scripting HTTP Requests Using Curl” to understand which client-side options reveal the actual HTTP exchange without changing its semantics unnecessarily.
In the opening explanation before “See the Protocol,” read the HTTP exchange to separate request line, headers, and body from the server response. In “See the Protocol,” focus on verbose output and then trace escalation. Use --trace-ascii only for a controlled request and store its output securely because it can capture sensitive headers or payloads. In the “URL” section, read host overrides so you can use --resolve to test a particular load-balancer IP while preserving the original hostname.
If the issue appears only in a browser, a basic curl request may not be equivalent. The browser might send cookies, an authorization token, a particular Origin header, a different user agent, or a preflight request. Compare browser developer-tools output with curl deliberately; do not blindly copy production credentials into shell history or ticket comments.
Separate a forward-proxy failure from an origin-side failure
A forward proxy is on the client’s side of the path. It can reject a request before the request ever reaches your load balancer or application.
For HTTPS, a standard explicit proxy typically receives a CONNECT host:443 request. If that succeeds, the client establishes TLS through the tunnel to the destination. A failure at this point can look very different from an origin HTTP error.
Common forward-proxy evidence includes:
| Observation | Strongest current interpretation | Next verification |
|---|---|---|
407 Proxy Authentication Required | The forward proxy requires authentication or the client did not send acceptable proxy credentials. | Check approved client proxy configuration and proxy authentication policy. |
Proxy-specific block page or 403 before TLS to the destination | Corporate policy, URL categorization, proxy ACL, or inspection policy may be blocking the request. | Correlate the time and request with forward-proxy logs. |
CONNECT succeeds, TLS and HTTP then fail | The forward proxy was traversed, but it may still affect the path through inspection or routing. | Compare with an approved direct-path test. |
| Direct path works but proxy path fails | The difference is localized to proxy policy, proxy egress, inspection, or proxy configuration. | Inspect proxy logs and configuration. |
| Proxy path works but direct path fails | Direct egress may be intentionally blocked, or the proxy uses a different egress route. | Do not treat bypassing the proxy as the permanent fix. |
When policy permits a comparison, force the proxy route explicitly:
curl --verbose \
  --proxy http://proxy.corp.example:3128 \
  "$url"
Then compare with a request that bypasses configured proxies:
curl --verbose \
  --noproxy '*' \
  "$url"
This is a diagnostic comparison, not a recommendation to bypass enterprise controls. A successful direct request only proves that the direct path behaves differently. It does not authorize applications to evade the corporate proxy.
A subtle but important point: proxy configuration can be injected through environment variables, container configuration, language-runtime settings, or sidecars. A curl test from a bastion host may therefore be a poor substitute for testing from the actual workload pod, VM, or CI runner.
Identify whether the load balancer, reverse proxy, or application generated the response
Once the client has received a valid HTTP response, collect two kinds of evidence in parallel:
- Response fingerprints, such as headers, body format, server banners, request IDs, and latency.
- Per-hop logs, matched by timestamp and correlation ID.
Headers can suggest a response source but should not be treated as proof. A header like server: nginx, via, x-cache, or a cloud-provider request ID may be added, stripped, or spoofed by an intermediary. A matched log event is stronger.
A useful evidence chain looks like this:
| Layer | What you want to establish |
|---|---|
| Load balancer access log | Did it receive the client request? Which rule and target group were selected? What response status did it send? |
| Target health | Were eligible backends considered healthy at that time? |
| Reverse-proxy access log | Did it receive the request from the load balancer? Which upstream did it select? |
| Reverse-proxy error log | Did upstream connection, header parsing, timeout, or reset errors occur? |
| Application log or trace | Did the application receive the request ID? If so, what status and duration did it record? |
Imagine this incident:
Client receives:          502 Bad Gateway
Load balancer log:        status=502, target_status=-
Reverse proxy error log:  connect() failed (111: Connection refused)
Application log:          no matching request
The application’s absence is meaningful only because the earlier layers show the request reached the reverse proxy and failed before an upstream connection could be created. The best conclusion is:
The reverse proxy accepted the request but could not establish a TCP connection to the selected application upstream. The load balancer returned the resulting 502 to the client. Verify application listener availability, endpoint selection, and proxy upstream configuration.
Contrast it with:
Client receives:          502 Bad Gateway
Load balancer log:        status=502, target_status=502
Reverse proxy access log: status=502, upstream_status=502
Application log:          outbound payment request failed with 502
Here the gateway code propagated from inside the application’s own dependency chain. Replacing or reconfiguring the public load balancer would be unjustified.
Load-balancer access logs are particularly valuable because many platforms record both the client-facing status and a backend or target status. Oracle’s load-balancer troubleshooting guide illustrates that distinction, while also emphasizing that 504 commonly represents an upstream proxy failing to connect or receive a response in time.
Troubleshooting Load Balancer HTTP Issues
Read Oracle Cloud Infrastructure’s “Troubleshooting Load Balancer HTTP Issues” as a vendor-specific example of using load-balancer access and error logs to distinguish an edge-generated gateway error from a status returned by a backend.
In “HTTP 502 Bad Gateway Errors,” begin at the logging guidance. Focus on the distinction between client-facing load-balancer status and backend status; field names differ across AWS, Azure, GCP, NGINX, and managed ingress products. Then read the “HTTP 504” explanation beginning the timeout interpretation. Treat this as a starting hypothesis and verify it with your own upstream logs and timeout settings.
Interpret status codes as clues, not verdicts
A practical first-pass classification is:
| Client-visible result | Likely boundary to investigate first | What would prove it |
|---|---|---|
| No HTTP status; curl reports connection or TLS error | Client, forward proxy, network, TLS listener | Curl verbose output, proxy behavior, TCP/TLS evidence |
301, 302, 307, 308 | Redirecting component | Location header and logs for each request |
400 | Edge, proxy, or application request validation | Error body, request/header size, malformed request evidence, matching logs |
401, 403 | Auth gateway, WAF, proxy policy, or application authorization | Identity/auth logs, WAF or proxy decision logs, application authorization record |
429 | Rate limiter or application quota | Rate-limit headers, limiter configuration, request-rate evidence |
500 | Application or intermediary failure | Application exception record; determine whether proxy merely passed it through |
502 | Gateway could not use its upstream, or an upstream itself sent 502 | Edge status plus target status; reverse-proxy error log; application trace |
503 | No healthy/capable backend, overload, maintenance, or application-generated unavailable response | Target health, deployment state, capacity, and application logs |
504 | Upstream response timeout in a proxy chain | Proxy timeout logs, upstream timing, dependency latency, timeout configuration |
A 400 deserves more respect than it often receives. If an incident occurs only for authenticated users with large cookies, an edge component may reject the request before it reaches the application because the headers exceed its limits. Compare the exact request headers from a successful and failing client, while redacting cookie and authorization values from incident artifacts.
Use controlled path comparisons without changing the request identity
At this stage, the goal is to hold as much as possible constant while changing one boundary at a time.
Pin a specific load-balancer address
If DNS returns multiple addresses, you may be observing an address-specific or availability-zone-specific failure. Pin a known address while retaining the hostname for the HTTP Host header, SNI, and certificate validation:
host='api.example.internal'
lb_ip='203.0.113.25'

curl --verbose \
  --resolve "${host}:443:${lb_ip}" \
  "https://${host}/v1/orders/123"
This proves behavior for that particular IP address at that time. It does not prove all load-balancer nodes behave identically.
Compare a public route with an internal upstream route
If you have authorized access to the private network, probe the backend only after recording the public-path failure. Preserve the expected host identity:
backend_ip='10.20.30.40'

curl --verbose \
  --resolve "${host}:443:${backend_ip}" \
  "https://${host}/v1/orders/123"
This test is only valid if the backend actually listens on the same port, serves TLS for that hostname, and is intended to accept direct traffic. Often it will not. A direct backend probe may bypass:
- WAF checks;
- authentication performed at the edge;
- path rewrites;
- TLS termination;
X-Forwarded-*header injection;- session-affinity routing;
- canary or weighted routing.
Therefore, interpret results carefully:
- Public fails, direct backend succeeds: the failure is likely in an intervening layer or its configuration, but compare headers and routing semantics before declaring the application healthy.
- Public succeeds, direct backend fails: direct access may be deliberately disallowed; this does not identify an incident.
- Both fail similarly and the application logs the request: application or a shared downstream dependency becomes more likely.
- Neither application nor reverse proxy logs the request: investigate earlier layers, route matching, listener policy, WAF, target health, and load-balancer logs.
Redirects require their own trace
A redirect response is successful HTTP communication, but it may lead users to a broken destination. First inspect the initial response without following it:
curl --silent --show-error \
  -D - \
  -o /dev/null \
  "$url"
Then follow the redirect chain separately:
curl --verbose \
  --location \
  --max-redirs 5 \
  -o /dev/null \
  "$url"
Look for an incorrect scheme, hostname, port, path prefix, or an internal host leaking into Location. Also check whether the redirect loops only when a forwarded-protocol header is missing or incorrectly set. A common example is an application believing the original request was plain HTTP because TLS terminated at the load balancer and X-Forwarded-Proto: https was absent or untrusted.
A repeatable incident and interview sequence
For a timed troubleshooting interview, avoid saying “I would check everything.” Use an ordered method that reduces the search space.
- Define the failed transaction. State the expected response, actual response, affected client location, hostname, path, method, and approximate UTC time.
- Reproduce once with curl verbose output. Record remote IP, proxy use, status, key response headers, and phase timings.
- Classify the boundary. Decide whether failure occurs before HTTP, at a forward proxy, as an HTTP response, or after a redirect.
- Add a safe correlation identifier. Use it to search load-balancer, proxy, application, and trace data in the same narrow time window.
- Check edge receipt and routing. Did the load balancer see the request? Which rule, target group, and target health state applied?
- Check reverse-proxy forwarding. Did it select an upstream? Did the upstream connection, response headers, and timeout behavior succeed?
- Check the application only when it received the request. Confirm request handling, authorization, errors, duration, and downstream calls.
- Run one controlled comparison. For example, explicit proxy versus approved bypass, one pinned load-balancer IP versus another, or public route versus authorized internal route.
- State the proven boundary and next action. Keep certainty proportional to the evidence.
An interview-quality summary might sound like this:
“I would first reproduce the exact request with
curl -vand record whether a forward proxy is involved, the remote endpoint, the HTTP status, response headers, and time to first byte. If I receive a 502 or 504, I would not assume the load balancer is the root cause. I would correlate a request ID and timestamp through load-balancer access logs, target-health data, reverse-proxy logs, and application logs. If the load balancer shows a target status but the application has no request record, I would focus on proxy-to-upstream connectivity, routing, or timeout behavior. If the application logged the request and returned the status, I would investigate application logic or its downstream dependency. I would use a pinned-IP or proxy-path comparison only after preserving the original hostname and request semantics.”
Key takeaways
- An HTTP failure must be located across client, forward proxy, load balancer, reverse proxy, and application boundaries.
curl -vwith timestamps provides a reproducible client-side account of proxy use, connection setup, request headers, response headers, status, and timing.- A client-visible HTTP code is evidence of the received response, not proof of where the root cause originated.
- Correlated logs are stronger than response headers alone. Match timestamps, request IDs, selected targets, upstream status, and application records.
502,503, and504are gateway and availability clues that require target-health, upstream, and application evidence before assigning blame.- Controlled comparisons should change one boundary at a time while preserving hostname, method, authentication, and other important request semantics.
- In an interview, lead with the boundary you can prove, then name the smallest next verification rather than guessing at root cause.
Next, you will practice communicating this hypothesis-driven troubleshooting method under time pressure: how to narrate observations, eliminate alternatives, and make sound decisions even when the available evidence is incomplete.
Can't find a good explanation? Sign up and we'll make it for you
Sign up