
Welcome back. You now have a monorepo boundary and a safe configuration boundary. The next boundary is the product’s domain model: the vocabulary and relationships that will keep the customer-support platform coherent as you add persistence, retrieval, AI responses, and agent workflows.
This lesson defines the first version of six closely related concepts: organization, knowledge source, conversation, message, and ticket. The key design decision is that an organization is the tenant boundary: all support data belongs to exactly one organization, and no workflow may cross that boundary.
By the end, you will have an implementation-ready conceptual ERD and a concise set of rules to record in docs/domain-model.md. We are defining the model, not yet writing SQLAlchemy tables or migrations.
Start with nouns, then decide what deserves an identity
A useful first pass over any product workflow is to identify the nouns:
A customer from an organization asks a question in a conversation. The AI and support agents add messages. The answer is grounded in uploaded knowledge sources. If the AI cannot resolve the issue, the conversation is escalated into a ticket.
Not every noun becomes a database entity. An entity should have its own:
- stable identity;
- lifecycle;
- relationships;
- independently meaningful history.
For example, a support message needs its own identity because it has an author, timestamp, visibility, content, and possibly later feedback or redaction. In contrast, a ticket’s priority is a property of the ticket, not an entity in its own right.
Watch this short segment from “Entity Relationship Diagrams” by Decomplexify to reinforce the progression from nouns, to relationships, to cardinalities.
“Entity Relationship Diagrams” by Decomplexify gives a practical method for translating product requirements into a small, defensible data model.
Watch identify entities to see how to refine nouns into meaningful entities. Continue with relationships, focusing on verbs such as “contains” and “belongs to.” Finish with cardinality, which explains why deciding whether something is optional, unique, or repeatable matters before creating tables.
For this capstone, the first-pass nouns become:
| Domain concept | Entity? | Why |
|---|---|---|
| Organization | Yes | It is the tenant and ownership boundary for all customer data. |
| Knowledge source | Yes | It has a file or URL, ingestion lifecycle, storage location, and retrieval eligibility. |
| Conversation | Yes | It is the durable thread of a customer-support interaction. |
| Message | Yes | It is an individually authored, ordered record in a conversation. |
| Ticket | Yes | It has its own operational lifecycle: assignment, priority, resolution, and human ownership. |
| Priority | No | It is a constrained property of a ticket. |
| Ingestion status | No | It is a constrained property of a knowledge source. |
| Message author role | No | It is a property such as customer, ai, agent, or system. |
| Knowledge chunk | Not yet | It will be a derived retrieval record in the ingestion and pgvector modules. |
That last choice is deliberate. A knowledge source is a customer-facing artifact, such as “Returns Policy.pdf.” Chunks and embeddings are processing outputs derived from that source. Introducing them now would blur a product-level model with a later retrieval implementation.
Organization is the tenant boundary
A tenant is a customer organization sharing the same application and database with other organizations while remaining isolated from them. In this product, an organization might be a company using the support platform for its own customers and support team.
The tenant boundary must be visible in the model, not merely assumed in frontend routing or a URL path. Every support artifact that contains organization-owned information will carry an organization_id.
Multi-Tenant SaaS Architecture in 3 Simple Steps
In “Multi-Tenant SaaS Architecture in 3 Simple Steps,” Jan Marshall explains the shared-application, shared-database model and why an organization identifier must partition each tenant’s records.
Watch tenant isolation. Focus on the distinction between sharing infrastructure and sharing data: tenants use the same application, but queries and authorization must remain scoped to a single organization identifier.
The initial Organization entity is intentionally small:
| Field | Purpose | Rule |
|---|---|---|
id | Stable organization identifier | UUID primary key |
name | Human-readable organization name | Required |
slug | URL-safe public identifier | Unique across the platform |
status | Whether the tenant can use the platform | Initially active or suspended |
created_at | Audit and reporting timestamp | UTC, set on creation |
updated_at | Last modification timestamp | UTC, updated on change |
Do not make name the identity. Names change, may be duplicated, and are not safe foreign keys. A UUID id is stable; a slug is convenient for URLs; a name is presentation data.
Tenant-scoping rule
Adopt this rule now:
Every knowledge source, conversation, message, and ticket belongs to exactly one organization. Any retrieved record must be filtered by the authenticated organization context.
This will matter later in several places:
- a retrieval query must not return another organization’s document chunks;
- an agent inbox must not list tickets belonging to another organization;
- a conversation URL must not expose a conversation by guessing its ID;
- API code must derive the organization context from authentication, rather than trusting a browser-supplied
organization_id.
At this stage, you are not implementing authentication yet. You are making the later authorization requirement possible through the domain shape.
Entities, value-like properties, and boundaries
An entity is not simply “a table.” It is a thing whose identity matters over time.
The Value Object within Aggregate diagram illustrates a useful distinction: an Order has an identity as an aggregate root; OrderItem has an identity within that order; an Address is value-like, represented by its attributes rather than an independent lifecycle.
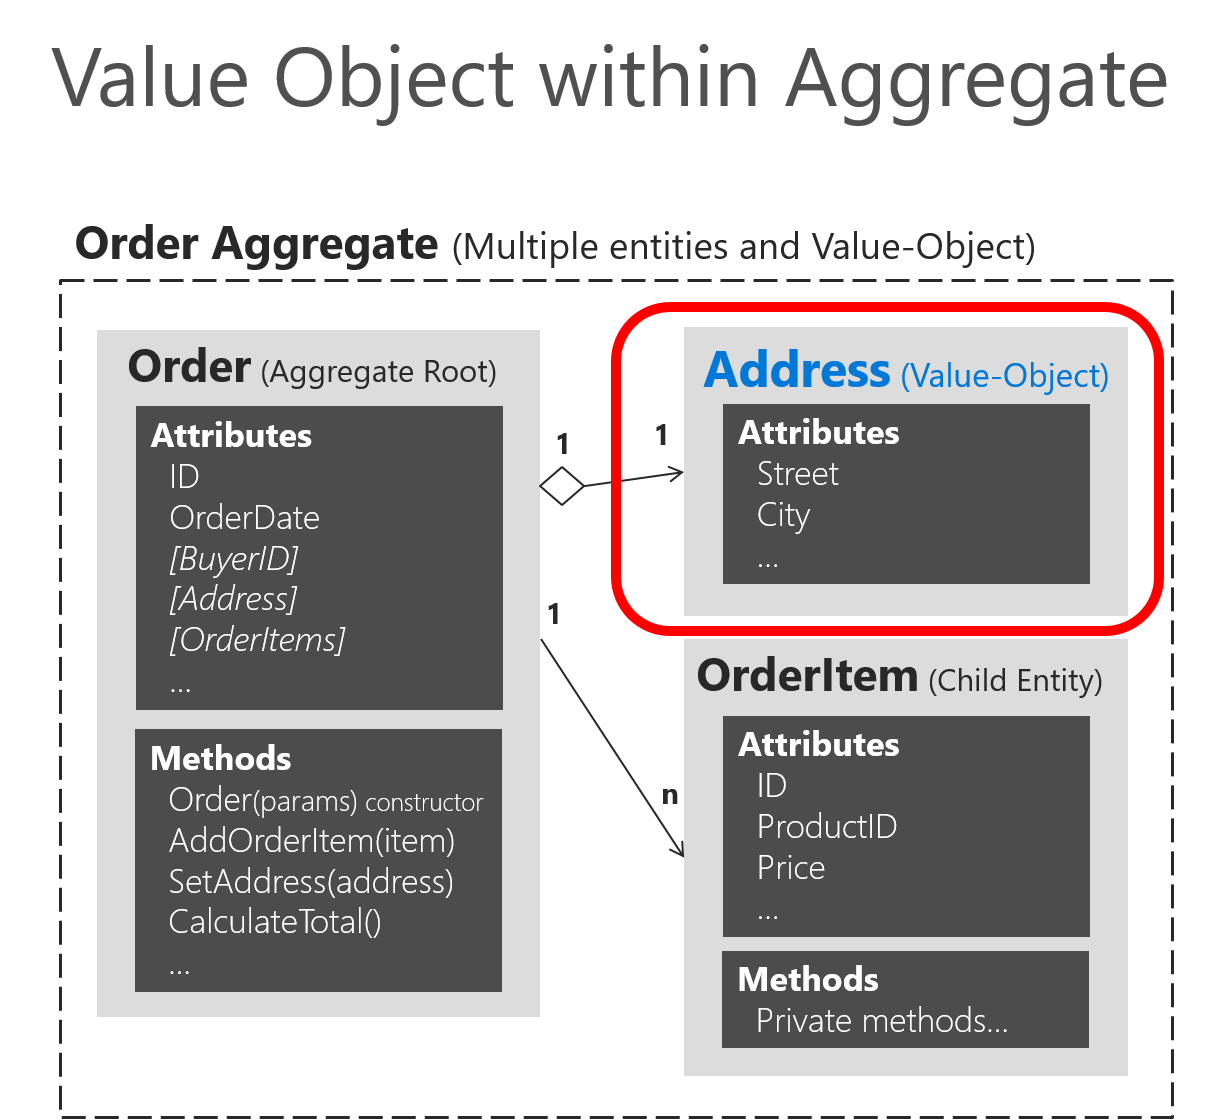
For the support platform:
- A conversation is a durable support thread with its own identity and status.
- A message is an entity because an individual message can be quoted, cited, hidden, corrected, or redacted without changing the identity of the conversation.
- A ticket is a separate operational entity. It references the conversation but adds agent-workflow concerns such as assignment and resolution.
priority,status,visibility, andsender_typeare controlled values. They should be modeled as application enums or constrained strings, not their own tables in version one.
This keeps the model expressive without prematurely building a generic workflow engine.
Define the customer interaction: conversations and messages
A conversation is the thread. A message is one item in that thread.
This distinction may sound obvious, but it prevents a common modeling mistake: placing a complete chat transcript into a single conversation.body field. That approach makes ordering, streaming, citations, agent notes, and later feedback difficult to represent correctly.
Intercom’s model offers a useful real-world reference: a conversation has a state, contacts, assignment information, and a set of individually authored conversation parts. It also separates customer-visible replies from internal notes and operational events.
Read Intercom’s conversation-model reference as an example of how a mature support product distinguishes a conversation thread from the individual parts within it.
In the “Conversation Object” section, read the conversation fields. Focus on lifecycle state, assignee, participants, and timestamps rather than copying every field. Then read the “Conversation Part Object” section, especially message records. Notice that author, body, timestamps, attachments, and redaction belong to individual parts. Finally, in “Conversation Part Types,” skim event types. For this capstone, replies, internal notes, and lightweight system events are enough; you do not need every advanced event type.
Conversation
A Conversation represents one customer-support thread for one organization.
| Field | Purpose | Rule |
|---|---|---|
id | Stable conversation identifier | UUID primary key |
organization_id | Tenant ownership | Required foreign key to Organization |
customer_ref | Opaque reference to the customer or external identity | Nullable for anonymous chat; never use an email address as the primary identity |
channel | Where the thread started | Initially web |
status | Current conversational state | open, waiting_on_customer, waiting_on_team, or closed |
last_message_at | Efficient inbox ordering | Updated when a message is appended |
created_at | Thread creation time | UTC |
updated_at | Last conversation-level change | UTC |
A customer may have many conversations, but this first model does not need a separate Customer entity. The application can store a safe opaque reference now and introduce a full customer identity model later if the product needs one.
Message
A Message is a durable timeline item within a conversation. It should cover normal replies, AI answers, internal agent notes, and minimal system-generated entries.
| Field | Purpose | Rule |
|---|---|---|
id | Stable message identifier | UUID primary key |
organization_id | Tenant ownership and defensive query filter | Required |
conversation_id | Parent thread | Required foreign key to Conversation |
sequence_number | Deterministic order inside one conversation | Required; unique per conversation |
sender_type | Who produced it | customer, ai, agent, or system |
sender_ref | Opaque reference to the sender where applicable | Nullable for AI and system messages |
kind | Meaning of the timeline item | reply, internal_note, or system_event |
visibility | Who may see it | public or internal |
body | Message content | Required for replies and notes |
created_at | Time appended to the thread | UTC |
redacted_at | When content was removed from normal display | Nullable |
The two fields most likely to prevent an expensive future correction are sequence_number and visibility.
Why not sort only by created_at? Two messages can receive the same timestamp resolution, especially during streaming or automated operations. A conversation-local sequence_number makes the intended order explicit and testable.
Why make visibility explicit? An agent’s internal note might include troubleshooting steps or an escalation rationale. That note must never be returned by the customer-facing conversation endpoint. sender_type="agent" does not answer whether a message is safe for the customer to see; visibility does.
A simple first set of message rules is:
- A message can be appended only to a conversation in the same organization.
- Every message receives the next available
sequence_numberfor that conversation. internal_notemessages must havevisibility="internal".- Customer-facing responses may return only
visibility="public"messages. - A redacted message retains its identifier and audit timestamp but should not expose its original body through normal APIs.
Define knowledge sources as owned, ingestible material
A Knowledge Source is a source document or maintained piece of content that the organization has authorized the AI to use as support evidence.
Examples include:
- an uploaded PDF return policy;
- a Markdown FAQ;
- HTML copied from a help-center article;
- a URL-based support article, if you later support URL ingestion.
It is not an embedding, a chunk, or a model response. It is the parent artifact those later records will trace back to.
| Field | Purpose | Rule |
|---|---|---|
id | Stable source identifier | UUID primary key |
organization_id | Tenant ownership | Required foreign key to Organization |
source_kind | Origin and processing path | file, url, markdown, or manual_text |
display_name | Name shown in the UI and citations | Required |
original_filename | Original upload name, when applicable | Nullable |
content_type | Declared or detected type | Nullable, such as application/pdf |
storage_key | Private object-storage reference | Nullable for inline content; never a public secret URL |
source_url | Canonical source URL, when applicable | Nullable |
checksum | Content identity for duplicate detection | Nullable until ingestion computes it |
ingestion_status | Processing lifecycle | uploaded, processing, ready, or failed |
failure_reason | Safe user-visible failure explanation | Nullable; never store raw stack traces or secrets |
created_at | Source creation time | UTC |
updated_at | Last source update | UTC |
The ingestion status is intentionally part of the source model. A source should not become eligible for retrieval merely because a file exists in storage. Only ready sources should provide evidence to the RAG pipeline.
For the initial lifecycle:
- A new upload begins as
uploaded. - A worker marks it
processingwhen extraction and chunking begin. - Successful extraction and embedding make it
ready. - A recoverable failure makes it
failed. - Retrying a failed source returns it to
processing, preserving its history and identity.
The checksum will become important when you implement idempotent ingestion. If the same logical source is submitted twice, you will have enough information to decide whether to reuse existing work or reprocess changed content.
Define tickets as agent-work records, not duplicate conversations
A ticket is an internal support-work record created when a conversation requires human handling. It does not replace the conversation and does not copy the whole transcript. The conversation remains the chronological customer interaction; the ticket is the agent’s operational view of the work.
Zendesk describes a comparable distinction: a request is the end user’s perspective, while a ticket is the agent and administrator perspective. That boundary fits this capstone well: customers participate in conversations, while agents triage and resolve tickets.
Tickets | Zendesk Developer Docs
Read the Zendesk ticket reference to see which properties belong to an agent-work record and why its perspective differs from a customer’s view.
In the “Tickets and Requests” and “Requesters and submitters” sections, read the ticket perspective. Focus on the difference between customer-facing communication and agent-managed work. Then find the “JSON format” table and inspect the rows named organization_id, priority, status, subject, requester_id, and submitter_id. Use them as vocabulary references, not as a requirement to reproduce Zendesk’s much larger enterprise model.
For this capstone, adopt a deliberately narrow rule:
A conversation may have zero or one current ticket. Every ticket belongs to exactly one conversation.
This fits the intended workflow: the AI initially handles the conversation; a deterministic handoff rule creates one ticket if an agent must intervene. If a future product requirement needs multiple separate cases from one conversation, you can revise this cardinality with a clear migration rather than accidentally permitting duplicates now.
| Field | Purpose | Rule |
|---|---|---|
id | Stable ticket identifier | UUID primary key |
organization_id | Tenant ownership | Required foreign key to Organization |
conversation_id | Conversation that required handoff | Required foreign key; unique in version one |
trigger_message_id | Message that triggered escalation | Nullable foreign key to Message |
title | Agent-readable summary label | Required |
handoff_reason | Explicit reason human handling is required | Required |
status | Work lifecycle | new, open, pending_customer, resolved, or closed |
priority | Operational urgency | low, normal, high, or urgent |
assignee_ref | Opaque reference to responsible agent | Nullable while unassigned |
created_at | Escalation time | UTC |
resolved_at | Resolution time | Nullable |
updated_at | Last ticket update | UTC |
Keep conversation status and ticket status separate:
- A conversation answers: What is happening in the customer interaction?
- A ticket answers: What work does the support team still need to perform?
For example, a customer conversation can be waiting_on_team while its ticket is open and assigned. An internal note can change the ticket’s assignee without becoming a public customer message.
The first conceptual ERD
The model now has five core entities and one tenant-scoping rule repeated across each tenant-owned record.
Read the cardinalities in plain language:
- One organization can own zero or many knowledge sources; each knowledge source belongs to one organization.
- One organization can have zero or many conversations; each conversation belongs to one organization.
- One conversation can contain zero or many messages; each message belongs to one conversation.
- One conversation can have zero or one ticket; each ticket refers to one conversation.
- Messages and tickets also store
organization_id, even though it can be derived through the conversation relationship.
That last point deserves care. The duplicate organization reference is useful for secure filtering and efficient queries, but it creates an invariant:
message.organization_idandticket.organization_idmust equal the organization of their parent conversation.
Later, database constraints and service-layer validation should enforce this rather than relying on convention.
Record the model before implementing it
Create docs/domain-model.md and record the following decisions in your own repository. This document is small, but it will make the first migration, API contract, and interview explanation much easier.
# Domain model

## Tenant boundary
Organization is the tenant. Knowledge sources, conversations, messages, and tickets
each belong to exactly one organization.

## Core entities
- Organization: tenant account and data boundary.
- KnowledgeSource: organization-owned support material with ingestion status.
- Conversation: customer-support thread.
- Message: ordered, authored timeline record inside a conversation.
- Ticket: internal agent-work record for an escalated conversation.

## Cardinality decisions
- Organization has many KnowledgeSources.
- Organization has many Conversations.
- Conversation has many Messages.
- Conversation has zero or one current Ticket.
- Each Ticket belongs to one Conversation.

## Invariants
- Tenant-owned records are always queried in organization scope.
- A Message organization must match its Conversation organization.
- A Ticket organization must match its Conversation organization.
- Message sequence numbers are unique within a Conversation.
- Internal notes are never returned to customer-facing clients.
- Only KnowledgeSources in ready status are eligible for retrieval.
Also make four explicit scope decisions:
- No user or membership table yet. Store opaque customer and agent references until authentication and membership are designed.
- No chunk or embedding entity yet. Those are derived records for the ingestion and retrieval modules.
- No separate generic event table yet.
system_eventmessages are sufficient for initial audit-visible timeline entries. - No automatic ticket duplication. The first version permits one current ticket per conversation.
These are not omissions. They are intentional limits that prevent the first schema from becoming a mixture of current requirements and speculative infrastructure.
Key takeaways
You now have a focused domain model for the AI customer-support platform:
- Organization is the multi-tenant ownership boundary.
- Knowledge Source represents customer-owned support material and its ingestion lifecycle.
- Conversation is the customer interaction thread.
- Message is an ordered, independently meaningful timeline record with explicit author type and visibility.
- Ticket is an internal agent-work record linked to, but distinct from, a conversation.
- Every tenant-owned record carries an
organization_id, and its consistency with parent records is a core invariant. - The model deliberately postpones users, chunks, embeddings, and detailed audit events until the product needs them.
Next, you will use the monorepo and configuration boundaries you have created to implement and verify a basic health-check request from the React application to the FastAPI service.
Can't find a good explanation? Sign up and we'll make it for you
Sign up