Hello! Welcome to your next lesson in the "Mathematical and Statistical Foundations for AI" module.
In our last lesson, we explored how matrix decomposition techniques like Eigendecomposition and SVD allow us to understand the fundamental structure of linear transformations. We concluded with the idea that while linear algebra provides the static "scaffolding" for AI models, the process of learning requires a different set of tools from calculus.
Today, we'll dive into those tools. This lesson covers how to compute partial derivatives and the gradient of multivariate functions. Your goal is to understand how we can measure the "slope" of a function with many inputs—like a neural network's loss function, which can depend on millions or even billions of parameters. This "slope," known as the gradient, is the single most important piece of information we need to train AI models, as it tells us exactly how to adjust our parameters to improve performance.
1. From Slopes to Slices: Introducing Partial Derivatives
From single-variable calculus, you'll recall that the derivative gives us the slope of the tangent line to a curve at any point . It tells us how the function's output changes for a tiny change in its input.
But what happens when a function has multiple inputs, like ? This function describes a surface in 3D space. At any point on this surface, there isn't just one "slope"; there are infinitely many, depending on the direction you move.
The core idea of multivariable calculus is to simplify this problem by asking a more constrained question: What is the slope if we only move along one axis at a time, keeping all other variables fixed? This is the concept of a partial derivative.
What Partial Derivatives Are (Hands-on Introduction) — Topic 67 of Machine Learning Foundations
To build a strong visual intuition for this, let's watch the first part of the video 'What Partial Derivatives Are' from Jon Krohn's Machine Learning Foundations series. He does an excellent job of visualizing a multivariate function and the idea of looking at its 'slices'.
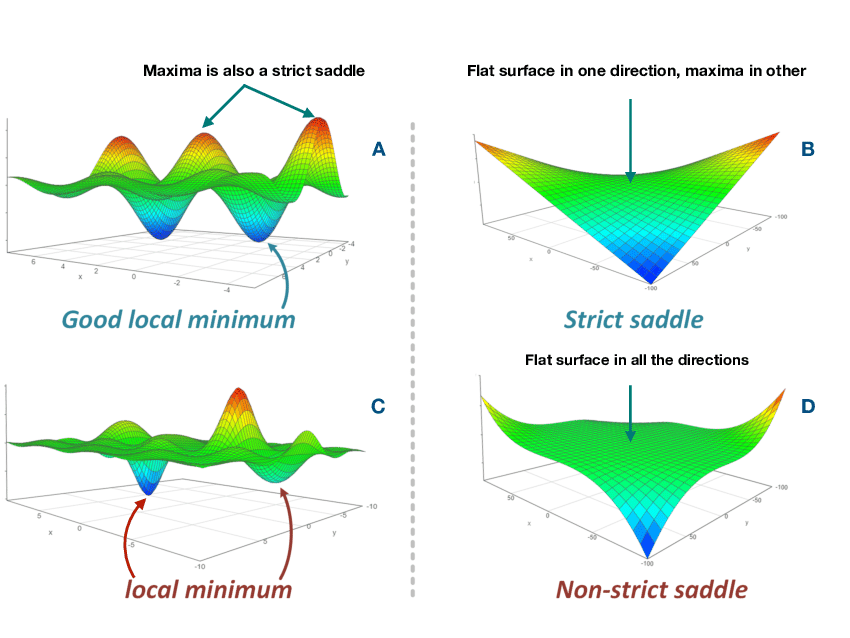
Watch from the beginning (00:14) to 04:22. Pay close attention to how he visualizes the function z = x² - y² as a 3D saddle shape and then orients the view to see how 'z' changes with 'x' alone.
As the video illustrates, by holding constant, we are effectively taking a 2D slice of the 3D surface. Within that slice, we have a simple curve whose slope we can find using standard single-variable differentiation rules.
The Calculation
To compute a partial derivative, you simply treat all variables—except the one you're differentiating with respect to—as constants.
Let's use the function from the video, .
To find the partial derivative with respect to :
We treat as a constant. The derivative of with respect to is . The derivative of (a constant) with respect to is 0.
So, the partial derivative of with respect to is:
The symbol (a curly 'd', often pronounced "del") is used to denote a partial derivative, distinguishing it from the ordinary derivative .
To find the partial derivative with respect to :
Now, we treat as a constant. The derivative of (a constant) with respect to is 0. The derivative of with respect to is .
So, the partial derivative of with respect to is:
What Partial Derivatives Are (Hands-on Introduction) — Topic 67 of Machine Learning Foundations
Let's continue with Jon Krohn's video as he walks through the formal calculation for ∂z/∂x and explains what the result means.
Watch from 04:22 to 08:23. This segment connects the visual 'slicing' to the symbolic calculation and introduces the ∂ notation.
Test your understanding!
Let . Find the partial derivatives and .
Show answer
For : Treat as a constant.
- The derivative of is .
- The derivative of is .
So, .
For : Treat as a constant.
- The derivative of is .
- The derivative of (a constant) is 0.
So, .
This process extends to functions with any number of variables. For , to find , you treat and as constants.
2. The Gradient: A Vector of Slopes
We can now calculate the slope of our function along each axis. But what if we want a complete picture of how the function changes at a point? We can combine all the partial derivatives into a single vector called the gradient.
For a function , the gradient, denoted (nabla f), is the vector of its partial derivatives:
The gradient is more than just a collection of partial derivatives; it has profound geometric meaning.
- It is a vector that points in the direction of the steepest ascent of the function at a given point.
- Its magnitude, , represents the rate of change in that steepest direction.
This is the key insight for machine learning. If points "uphill," then must point in the direction of steepest descent—the most efficient way to go "downhill."
This is the mathematical foundation of gradient descent, the workhorse optimization algorithm for training almost all modern AI models. We calculate the gradient of the loss function with respect to the model's parameters (weights), and then take a small step in the opposite direction of the gradient to update those parameters.
Geometry of Gradients and Gradient Descent
The textbook 'Dive into Deep Learning' provides a concise and formal explanation of how the gradient is used in the gradient descent algorithm. This will solidify the connection between the math and its application in AI.
Read the sections 'Higher-Dimensional Differentiation' and 'Geometry of Gradients and Gradient Descent'. Focus on how the gradient arises from approximating the function's change (Eq. 18.4.5) and why its negative direction is chosen for optimization.
The text formalizes the gradient descent update rule:
Here, is the vector of our model's weights, is the loss function, is the gradient of the loss with respect to the weights, and (epsilon) is a small positive number called the learning rate.
3. Visualizing Gradients in Python
Let's ground these concepts in code. Your proficiency in Python makes it the perfect tool to bridge the gap between abstract formulas and concrete results. We'll revisit the function and use Python to not only calculate its partial derivatives but also to visualize the tangent lines whose slopes they represent.
The video by Jon Krohn includes a detailed code walkthrough. I'll summarize the key logic here, but you can refer to the video for a line-by-line explanation.
Core Logic of the Python Demo
-
Define the function and its partial derivatives:
import numpy as np # The multivariate function def f(x, y): return x**2 - y**2 # The partial derivative of f with respect to x def del_f_del_x(x, y): return 2*x # The partial derivative of f with respect to y def del_f_del_y(x, y): return -2*y -
Analyze the partial derivative with respect to x:
- To visualize the slice where is constant, we can fix
y=0. - We can then plot , which is a simple parabola.
- At any point on this parabola, say
x = -1, the slope of the tangent line should be given by our partial derivative function:del_f_del_x(-1, 0) = 2*(-1) = -2. - We can plot this tangent line to visually confirm our calculation.
- To visualize the slice where is constant, we can fix
-
Analyze the partial derivative with respect to y:
- Similarly, to visualize the slice where is constant, we fix
x=0. - We plot , which is an inverted parabola.
- At any point, say
y = 1, the slope isdel_f_del_y(0, 1) = -2*1 = -2.
- Similarly, to visualize the slice where is constant, we fix
The full code in the video generates plots that show these curves and their tangent lines, providing a powerful visual confirmation of the math.
Partial Derivatives and the Gradient of a Function
Professor Dave Explains provides a compact summary of calculating the gradient for a couple of example functions. Watch this to see the whole process put together.
Watch from 03:28 to 07:10. This segment demonstrates the calculation of partial derivatives for a new function and then assembles them into the gradient vector, explaining its meaning.
Conclusion
Today, we've taken a crucial first step into the calculus that powers machine learning. You now have the tools to analyze how a function with many variables changes.
Key Takeaways:
- A partial derivative measures the instantaneous rate of change of a multivariate function along one specific axis, holding all other variables constant.
- The gradient, , is a vector containing all the partial derivatives. It points in the direction of the function's steepest increase.
- The negative gradient, , points in the direction of steepest decrease. This is the core principle behind the gradient descent algorithm, which is used to minimize loss functions and train AI models.
Preview of the next lesson:
The functions we dealt with today were relatively simple. Neural networks, however, are deeply nested, composite functions. For example, the loss is a function of the final activation, which is a function of the pre-activation sum, which is a function of the weights and the previous layer's activations, and so on.
To calculate the gradient of the loss with respect to a weight deep inside the network, we can't just apply simple derivative rules. We need a systematic way to handle these nested functions. This method is the multivariate chain rule, and its algorithmic implementation in deep learning is the famous backpropagation algorithm. In the next lesson, we will derive and apply the chain rule, which will prepare us to build a neural network from scratch.