
Good to see you again. In the previous lesson, you converted the behavioral-detection platform’s workload assumptions into explicit capacity constraints: events per second at normal peak, during the modeled attack burst, approximately TB of allocated event-log disk, and a benchmark target rather than an assumed node count.
Those numbers now need to influence a durable architectural choice. This lesson shows how to record that choice in an architecture decision record (ADR): a concise, reviewable account of what was decided, why it was appropriate under the conditions known at the time, and what commitments or costs follow.
By the end, you will have a proposed ADR for placing a durable event log between telemetry ingestion and detection processing. The emphasis is not on producing documentation for its own sake; it is on creating a decision artifact that can survive staff changes, architecture reviews, incident retrospectives, and future revisions.
An ADR records a decision, not a design diary
An ADR is a small, append-only entry in the architecture’s decision log. Its job is to preserve a specific answer to a consequential question:
Given these constraints and alternatives, what did we choose, and what are we now committed to?
That is different from a design document.
- A design document can explore several ideas, include diagrams, evolve substantially, and explain implementation details.
- An ADR captures one settled choice at a point in time. It should be brief, assertive, and useful even when the associated design document has become stale.
- A ticket tracks work. It should link to an ADR when that work implements, or potentially violates, an architectural decision.
For a principal-level backend architecture, ADRs are particularly useful because important constraints are rarely visible in code alone. A future engineer might see a partitioned event log and wonder why the platform did not send telemetry directly from connectors to Detection Workers. The ADR should make the answer discoverable without relying on someone’s memory.
Architecture Decision Records (ADR) as a LOG that answers "WHY?"
Watch Architecture Decision Records (ADR) as a LOG that answers "WHY?" from CodeOpinion. It gives a compact explanation of the ADR as a lightweight historical record rather than a static architecture manual.
Watch the core structure. Focus on the distinction between recording a decision’s current status, its surrounding context, and its consequences. Notice the emphasis on keeping ADRs close to source code in an append-only log.
What is consequential enough to deserve an ADR?
Do not create an ADR for every local implementation preference. The test is whether a choice has a meaningful architectural blast radius. Record it when it does one or more of the following:
- changes system structure or an important boundary;
- materially affects security, availability, recovery, cost, latency, or scalability;
- creates a cross-service dependency or published contract;
- is difficult or expensive to reverse after implementation;
- constrains future teams’ implementation choices.
For the telemetry platform, these are ADR-worthy:
| Choice | Why it is consequential |
|---|---|
| Insert a durable event log between ingestion and detection | Changes failure behavior, scaling, recovery, storage, and operations. |
| Select a tenant-isolation strategy | Shapes security boundaries and data-access guarantees. |
| Define service-to-service workload identity | Shapes trust boundaries throughout the backend. |
| Use an outbox for event publication | Establishes delivery and consistency behavior across data stores. |
These ordinarily are not ADR-worthy on their own:
- renaming an internal Rust module;
- choosing a local helper function;
- changing a dashboard query;
- correcting a non-behavioral API response message.
The distinction is not about the number of lines changed. It is about the duration and scope of the constraint introduced.
ADR process - AWS Prescriptive Guidance
Read AWS Prescriptive Guidance’s Architectural decision record process for a practical definition of ADR scope, minimum content, ownership, and review lifecycle.
In “Scope of the ADR process” and “ADR contents,” read the scope and core contents. Focus on why structure, quality attributes, dependencies, interfaces, and construction techniques can all be architecturally significant. Then move to “ADR adoption process.” Read ownership and review, then continue through the discussion of Proposed, Accepted, and Rejected states. Pay particular attention to the owner’s responsibility for resolving review actions and preserving a rejection rationale.
The anatomy of a reviewable ADR
A minimal ADR needs four things:
- Status — whether the record is Proposed, Accepted, Rejected, or Superseded.
- Context — the facts, constraints, decision drivers, and relevant uncertainty.
- Decision — one unambiguous statement of what the team will do.
- Consequences — both the advantages gained and the obligations, costs, or risks accepted.
A stronger practical template adds metadata, options considered, confirmation criteria, and review triggers.
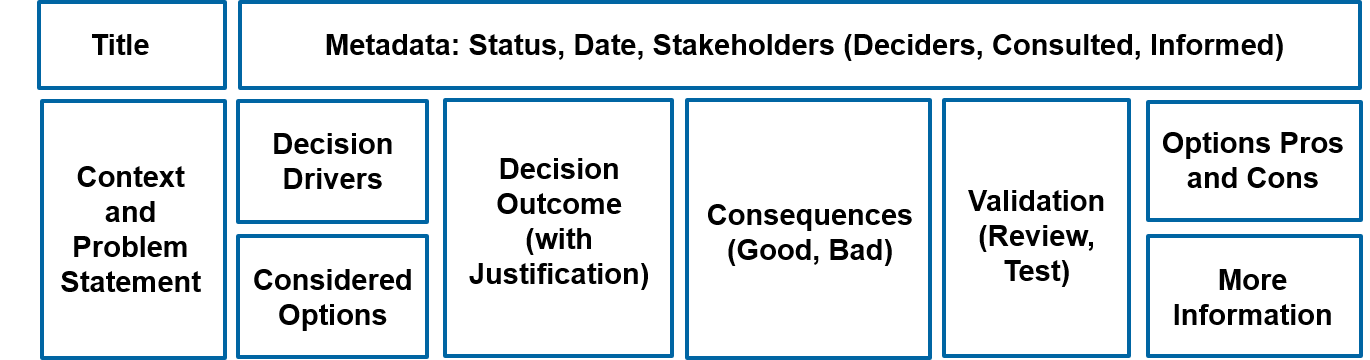
The key discipline is one ADR, one decision. Consider these two titles:
- Poor: “Telemetry architecture”
- Better: “Use a durable event log between telemetry ingestion and detection”
The first could conceal decisions about schemas, retention, broker products, tenant partitioning, delivery guarantees, and alerting. The second is narrow enough to evaluate. The specific event-log product, partition key, consumer delivery semantics, and event schema can each receive their own ADR later if they are consequential.
Separate facts, assumptions, and decisions
This separation is where many otherwise experienced teams lose clarity.
| Category | Example for this platform | How to write it |
|---|---|---|
| Fact or accepted constraint | The current container design separates the Telemetry Connector from the Detection Worker. | State it plainly and link supporting material in the repository where available. |
| Planning assumption | The modeled attack peak is events per second for fifteen minutes. | Label it as an assumption and state its source. |
| Decision driver | Detection processing must be restartable and independently scalable from ingestion. | Explain why it matters to the choice. |
| Decision | Use a replicated, partitioned durable event log for normalized telemetry. | Make it definitive and testable. |
| Consequence | The platform now needs log-cluster capacity, access controls, monitoring, and replay procedures. | Treat it as an obligation, not an afterthought. |
A common failure mode is to write the decision as if it were a fact: “Kafka is used for events.” That loses both the choice and its reasoning. Another is to present a preference as rationale: “We chose Kafka because Kafka is scalable.” That says little about the actual system constraints, alternatives, or evidence.
ADRs have a lifecycle
An ADR should normally begin as Proposed. That status means it is ready for review, but the architecture has not yet committed to it. Reviewers should be able to challenge its assumptions, rejected alternatives, consequences, and confirmation plan.

Use the statuses precisely:
| Status | Meaning | What happens next |
|---|---|---|
| Proposed | A decision is recommended but not yet approved. | Review, resolve actions, validate evidence. |
| Accepted | The team has committed to the decision. | Implement it, and use it in code and design reviews. |
| Rejected | The team explicitly declined the proposal. | Retain the reason so the same debate is not repeatedly reopened. |
| Superseded | A later accepted ADR replaced this decision. | Link to the newer ADR; preserve the older record as history. |
An accepted ADR is not a living document that gets rewritten whenever circumstances change. If the platform later needs a different architecture, create a new ADR that states the new context and decision, then mark the old record as Superseded. This preserves the reasoning that was sound under earlier conditions and makes the change in direction auditable.
Write the proposed event-log decision
The capacity model from the previous lesson gives this ADR meaningful context. It does not automatically select an architecture. It gives evidence that an architecture must address:
- normal and attack traffic;
- durable buffering when downstream detection slows or restarts;
- multi-day replay capacity;
- independent scaling of connectors and workers;
- operational storage and network costs.
The following is a deliberately cloud-neutral ADR. It chooses an architectural capability, not a specific managed service or self-hosted broker. That distinction keeps the decision properly scoped.
# ADR-006: Use a durable event log between telemetry ingestion and detection

- **Status:** Proposed
- **Owner:** Platform Architecture
- **Stakeholders:** Detection Engineering, Ingestion Engineering, Security Engineering,
  Site Reliability Engineering
- **Decision date:** Pending review
- **Confidence:** Medium

## Context

The Tenant Behavioral Detection Platform collects security telemetry from external
identity providers. The Telemetry Connector normalizes source events, archives raw
evidence, and forwards normalized events for detection processing.

The current planning model estimates:

- approximately 1.0 billion normalized events per day;
- a normal peak of 48,000 events per second;
- an attack peak of 144,000 events per second for 15 minutes;
- three days of normalized-event retention;
- approximately 14 TB of allocated replicated event-log disk under the current
  attack and free-space assumptions.

Detection processing can be slower than ingestion during an incident, worker restart,
deployment, or downstream dependency failure. Connectors and Detection Workers must
be deployable and scalable independently. The platform also needs a controlled way to
replay normalized events after detection defects or processing failures.

The workload estimates and retention values are planning assumptions, not production
measurements. They must be validated with representative telemetry.

## Decision drivers

- Preserve normalized telemetry while Detection Workers are unavailable or lagging.
- Decouple connector throughput from detection-processing throughput.
- Support bounded replay without recollecting data from an external source.
- Scale ingestion and detection independently.
- Maintain a clear operational ownership boundary for retained telemetry.
- Avoid making the Telemetry Connector depend on the availability of individual
  Detection Worker instances.

## Options considered

1. Send normalized events directly from each Telemetry Connector to Detection Workers.
2. Use a general-purpose durable work queue between connectors and workers.
3. Use a replicated, partitioned durable event log with time-based retention.

## Decision

We will place a replicated, partitioned durable event log between the Telemetry
Connector and Detection Workers.

The Telemetry Connector will publish normalized events to the event log after applying
the required validation and normalization. Detection Workers will consume events from
the log independently of connector deployment and scaling.

The event log will retain normalized events for three days under the current planning
model. Raw evidence archival remains a separate responsibility and is not replaced by
the event log.

This ADR does not select a specific broker product, cloud service, partition key,
delivery semantic, or event-schema format. Those decisions will be evaluated
separately where their consequences warrant their own ADRs.

## Rationale

Direct connector-to-worker delivery couples collection availability to detection
availability and makes burst absorption, worker recovery, and replay difficult.

A general-purpose work queue can decouple components, but this decision requires
multi-day retained telemetry and controlled replay as first-class capabilities.
A partitioned event log is selected because it makes retained ordered streams and
independent consumer progress explicit architectural responsibilities.

## Consequences

### Positive

- Connector and Detection Worker fleets can scale and deploy independently.
- Detection processing can recover from restart or defect through bounded replay.
- Attack bursts can be durably buffered while workers catch up.
- Retention and replay become explicit, measurable platform capabilities.

### Negative and obligations

- The platform must operate or procure a durable event-log service, including
  replication, capacity, access control, monitoring, and incident procedures.
- Under current assumptions, the event log requires approximately 14 TB of allocated
  replicated storage; this estimate must be revalidated with production-like data.
- The platform must define partitions, consumer behavior, deduplication, and
  authorization controls in later design work.
- Retained normalized telemetry increases the security and privacy scope of the
  platform and requires a formal data-classification and retention review.
- Replay can reproduce side effects unless downstream processing is designed to be
  idempotent.

## Confirmation

Before acceptance, demonstrate all of the following with representative event shapes:

- ingestion accepts the modeled attack peak of 144,000 events per second with the
  agreed operational headroom;
- the event log retains three days of traffic while respecting the free-space policy;
- Detection Workers can restart and resume processing from a controlled position;
- connector failures, worker failures, and event-log unavailability have documented
  operational responses;
- access to retained telemetry is limited to authorized platform workloads.

## Review triggers

Revisit this decision if any of the following occur:

- planned peak volume or retention changes materially;
- the required detection-latency objective cannot tolerate the measured backlog delay;
- a source requires ordering or delivery guarantees that the selected log cannot meet;
- security classification or residency requirements prohibit the proposed retention
  approach;
- operating cost or incident evidence shows that a different buffering architecture
  is justified.
Why this draft is credible
The decision statement is deliberately short:
“We will place a replicated, partitioned durable event log between the Telemetry Connector and Detection Workers.”
Everything else supports, bounds, or tests that statement.
Notice several decisions that the ADR does not sneak in:
- It does not claim a particular broker is the winner.
- It does not select a partition key.
- It does not define exactly-once, at-least-once, or another delivery semantic.
- It does not make raw evidence archival dependent on the event log.
- It does not pretend that capacity estimates are production measurements.
That restraint matters. An ADR that bundles too many decisions becomes hard to review because an objection to one detail can block the entire record. It also becomes hard to supersede safely later.
Make the consequences operational
A weak consequence section says, “This improves scalability but adds complexity.” That is true of many architectures and useful to almost no one.
A useful consequence names what the team must now own. For the selected event-log architecture, that includes:
- capacity ownership: disk, replication, free-space policy, and network throughput;
- security ownership: service authorization, encryption configuration, auditability, and data retention;
- recovery ownership: replay procedures, consumer restart behavior, and backlog alerting;
- delivery ownership: subsequent decisions about duplicate handling and processing side effects;
- cost ownership: retained-data costs, cross-zone traffic where applicable, and operational support.
The confirmation section turns the ADR from an assertion into a falsifiable proposal. The previous lesson’s figures become especially useful here:
| ADR claim to validate | Evidence required |
|---|---|
| The platform can ingest the attack burst. | A representative benchmark at events per second, including validation, serialization, TLS, and actual broker writes. |
| The log can provide three days of retained replay. | Measured record size, retention behavior, replication footprint, and a verified free-space policy. |
| Detection can recover after disruption. | A controlled worker restart and replay test with queue lag, p95 and p99 processing latency, and recovery time recorded. |
| The decision supports the product’s detection journey. | A defined detection-latency SLO, then evidence that burst backlog remains within its allowed delay budget. |
The ADR does not need to contain every benchmark output. It should state what evidence determines whether the proposal is safe to accept, and it should link to the benchmark report or capacity model in the repository.
Before submitting an ADR for review, perform a concise editorial pass:
- Remove implementation details that do not alter the decision.
- Label assumptions rather than presenting them as established facts.
- Make every alternative genuinely distinct.
- State the decision using a clear “We will…” sentence.
- Name at least one disadvantage or obligation that the team must accept.
- Define what evidence would challenge or validate the proposal.
- Identify the conditions that should trigger reconsideration.
Key takeaways
An ADR is a compact record of a consequential architectural choice and its reasoning at a particular point in time.
For the behavioral-detection platform, placing a replicated durable event log between telemetry ingestion and detection is consequential because it changes the platform’s structure, recovery model, scalability, storage costs, and security responsibilities. A useful ADR:
- isolates that one decision from related future decisions;
- distinguishes facts, assumptions, drivers, decisions, and consequences;
- records meaningful alternatives rather than a foregone conclusion;
- begins as Proposed and becomes Accepted only after review and evidence;
- stays immutable after acceptance, with future changes expressed through a superseding ADR;
- defines confirmation criteria and review triggers so the architecture can be reassessed responsibly.
Next, you will compare architecture alternatives with a weighted trade-off matrix. That method will give a more explicit and repeatable way to evaluate options such as direct delivery, a work queue, and a retained event log before finalizing an ADR.
Can't find a good explanation? Sign up and we'll make it for you
Sign up