
Welcome to Week 4. Until now, the focus has been designing bounded Jev judgments and placing them inside deterministic application workflows. This week shifts from “does the integration work?” to “can we demonstrate that it makes dependable decisions on the cases our application will actually receive?”
For a Jev workflow, an evaluation dataset is an executable specification: each row preserves the evidence supplied to a question, the decision the product should make, and the outcome of human review. By the end of this lesson, you will have a practical schema and labeling process for a held-out support-routing dataset that can later measure accuracy, automation coverage, calibration, and regressions.
Plan for roughly 40 minutes: study two short resources, define the dataset contract, and create the first version of a JSONL dataset in TypeScript.
1. What a labeled evaluation dataset must capture
A log is not automatically an evaluation dataset. Logs tell you what happened; an eval dataset tells you what should happen under a frozen decision contract.
For each representative state, your dataset needs three things:
- State — the evidence Jev was allowed to use.
- Expected decision — the correct typed judgment and its deterministic business action.
- Review outcome — how a qualified reviewer arrived at, confirmed, corrected, or rejected that label.
For a support intent router, a compact contract could be:
| Element | Example |
|---|---|
| Atomic Jev question | “Which supported support intent best describes this request?” |
| Choice options | order_status, return_policy, technical_issue, cancel_order, other |
| Deterministic action | Route to a specialist queue, or send other to human review |
| State evidence | User message, relevant conversation context, locale, authenticated context if it changes the route |
| Gold decision | technical_issue |
| Gold action | route_technical |
| Review outcome | confirmed by two reviewers |
The key separation is:
| Dataset field | Meaning | Created when |
|---|---|---|
expected | The gold decision and deterministic action | Dataset labeling |
review | Evidence that a person confirmed, corrected, or rejected the label | Dataset labeling |
actual | A later Jev response: selected option, probabilities, confidence, latency | Evaluation run |
run_review | Human judgment of a specific model run, especially a failure | After an evaluation or production review |
Do not put a prior model answer into the state and then ask reviewers whether that answer was good. That causes anchoring and can turn a model’s mistake into supposed ground truth. Reviewers should first label the state against the decision contract; model outputs are compared with that label afterward.
Evaluation best practices | OpenAI API
Read OpenAI’s “Evaluation best practices” to frame dataset construction as one stage in an ongoing evaluation loop, rather than a one-off testing task.
In the “Design your eval process” section, read the five step workflow. Focus on the ordering: define success first, collect appropriate data second, then decide how it will be measured. For this lesson, the dataset is the concrete output of the collection stage.
The important consequence is that labels depend on a versioned contract. If you later add a billing_issue option, change the wording of the question, or alter the deterministic action for other, you have changed the system under evaluation. Preserve the old dataset and make a new dataset version rather than silently relabeling history.
2. Start with a decision contract, not a pile of examples
Before collecting cases, write down what one dataset row is intended to prove. Keep the scope narrow enough that a reviewer can make a reliable judgment.
For the support router, define the contract in plain language:
Given the sanitized customer message and listed context, select exactly one support intent. If none of the supported intents applies clearly, select
other. The application routes supported intents to their queues and sendsotherto human review.
This is a useful Jev evaluation target because it is bounded: there is a finite set of choices and a clear operational consequence for each choice.
The contract should also state what is not being judged. For example:
- It is not judging whether the final support response is polite or helpful.
- It is not extracting an order number.
- It is not deciding whether a refund should be approved.
- It is not inventing a new category outside the allowlisted options.
Those could be separate decisions with their own datasets. Combining them in one label makes failure analysis much harder: a wrong route, an invalid extraction, and an unsafe action would all look like one vague “bad result.”
Expected decisions include the deterministic application policy
A Jev output is a model judgment. Your product behavior should be determined by that judgment plus explicit application code.
For this router:
| Expected intent | Deterministic application action |
|---|---|
order_status | route_order |
return_policy | route_returns |
technical_issue | route_technical |
cancel_order | route_cancellation |
other | human_review |
Storing both the expected intent and action makes the dataset readable, but the action should be mechanically checked against the intent. Otherwise a row can accidentally contain a correct model label and an inconsistent business action.
3. Make the dataset representative — including the cases you should decline to automate
A dataset made entirely of clear, happy-path messages can report impressive accuracy while failing in production. Representative does not mean “randomly copy a few tickets.” It means deliberately covering the combinations of input and context that affect your decision.
Use a small coverage matrix before you collect examples:
| Coverage slice | Why it belongs in the dataset | Support-router example |
|---|---|---|
| Clear supported requests | Establish baseline performance per intent | “Where is order 2024-1198?” |
| Unsupported requests | Test whether other is selected rather than guessed | “Can you add a new payment card for me?” |
| Boundary cases | Expose ambiguity between nearby options | “Can I stop an order that is already being packed?” |
| Noisy input | Represents ordinary user behavior | “cncl my ordrr pls” |
| Minimal context | Tests whether the system avoids overconfident inference | “My order” |
| Multiple intents | Tests the policy for compound requests | “Cancel my order, and what is your returns policy?” |
| Long or distracting context | Checks whether salient evidence is still used correctly | A long thread ending with a new cancellation request |
| Language or format variants | Needed only for inputs your product supports | Russian or English messages; pasted JSON error details |
| High-impact failures | Receives deliberate oversampling | Requests involving account access or urgent cancellation |
Include both covered and uncovered cases. In this router, other is the legitimate “nothing supported applies” result. Without these negative cases, a system can appear accurate by always forcing a request into the nearest available route.
Skill suggestion - TypeSafe AI
Read the TypeSafe AI cookbook’s dataset design example. It demonstrates why an evaluation set must include requests that should produce no automated selection, not only examples that match a supported capability.
In “Step 2: score the agent on its own,” focus on the rationale for uncovered cases. Translate that idea to your router: unsupported requests should receive the gold intent other, rather than being omitted from the dataset.
A sensible initial data mix is:
- Production or historical cases, sanitized and sampled across real routes and outcomes.
- Human-curated cases, especially boundary conditions and high-impact incidents.
- Synthetic cases, used to fill known gaps, such as typos, terse wording, or a supported language variant.
Synthetic examples are useful for coverage, but do not let generated examples become your only data source. They often reflect the assumptions in the prompt that generated them, rather than the ways real users communicate.
4. Use a review process that creates defensible labels
A label such as technical_issue is only meaningful if another person can understand how it was reached. Make review outcomes first-class data rather than informal comments in a spreadsheet.
Use these review statuses:
| Review outcome | Meaning | Include in accuracy metric? |
|---|---|---|
confirmed | Reviewer agrees with the initial label | Yes |
corrected | Reviewer changed the initial label after applying the contract | Yes |
ambiguous | The contract reasonably permits more than one decision | No; retain for analysis |
insufficient_evidence | State lacks information required to label it | No; fix the state or exclude it |
out_of_scope | Case does not belong to this workflow | No; move to another dataset if needed |
A practical labeling protocol is:
- Freeze the question wording, options, and action mapping.
- Give the reviewer only the sanitized state and the contract.
- Have the reviewer choose the expected Jev value and resulting action.
- Require a short rationale focused on observable evidence.
- Send boundary, high-impact, or disputed cases to a second reviewer.
- Record whether adjudication confirmed or corrected the original label.
- Keep ambiguous cases, but exclude them from the denominator of exact accuracy.
The following diagram shows the longer-term use of this process: broad scoring supplies coverage, while focused deeper review supplies explanations and new labeled examples.
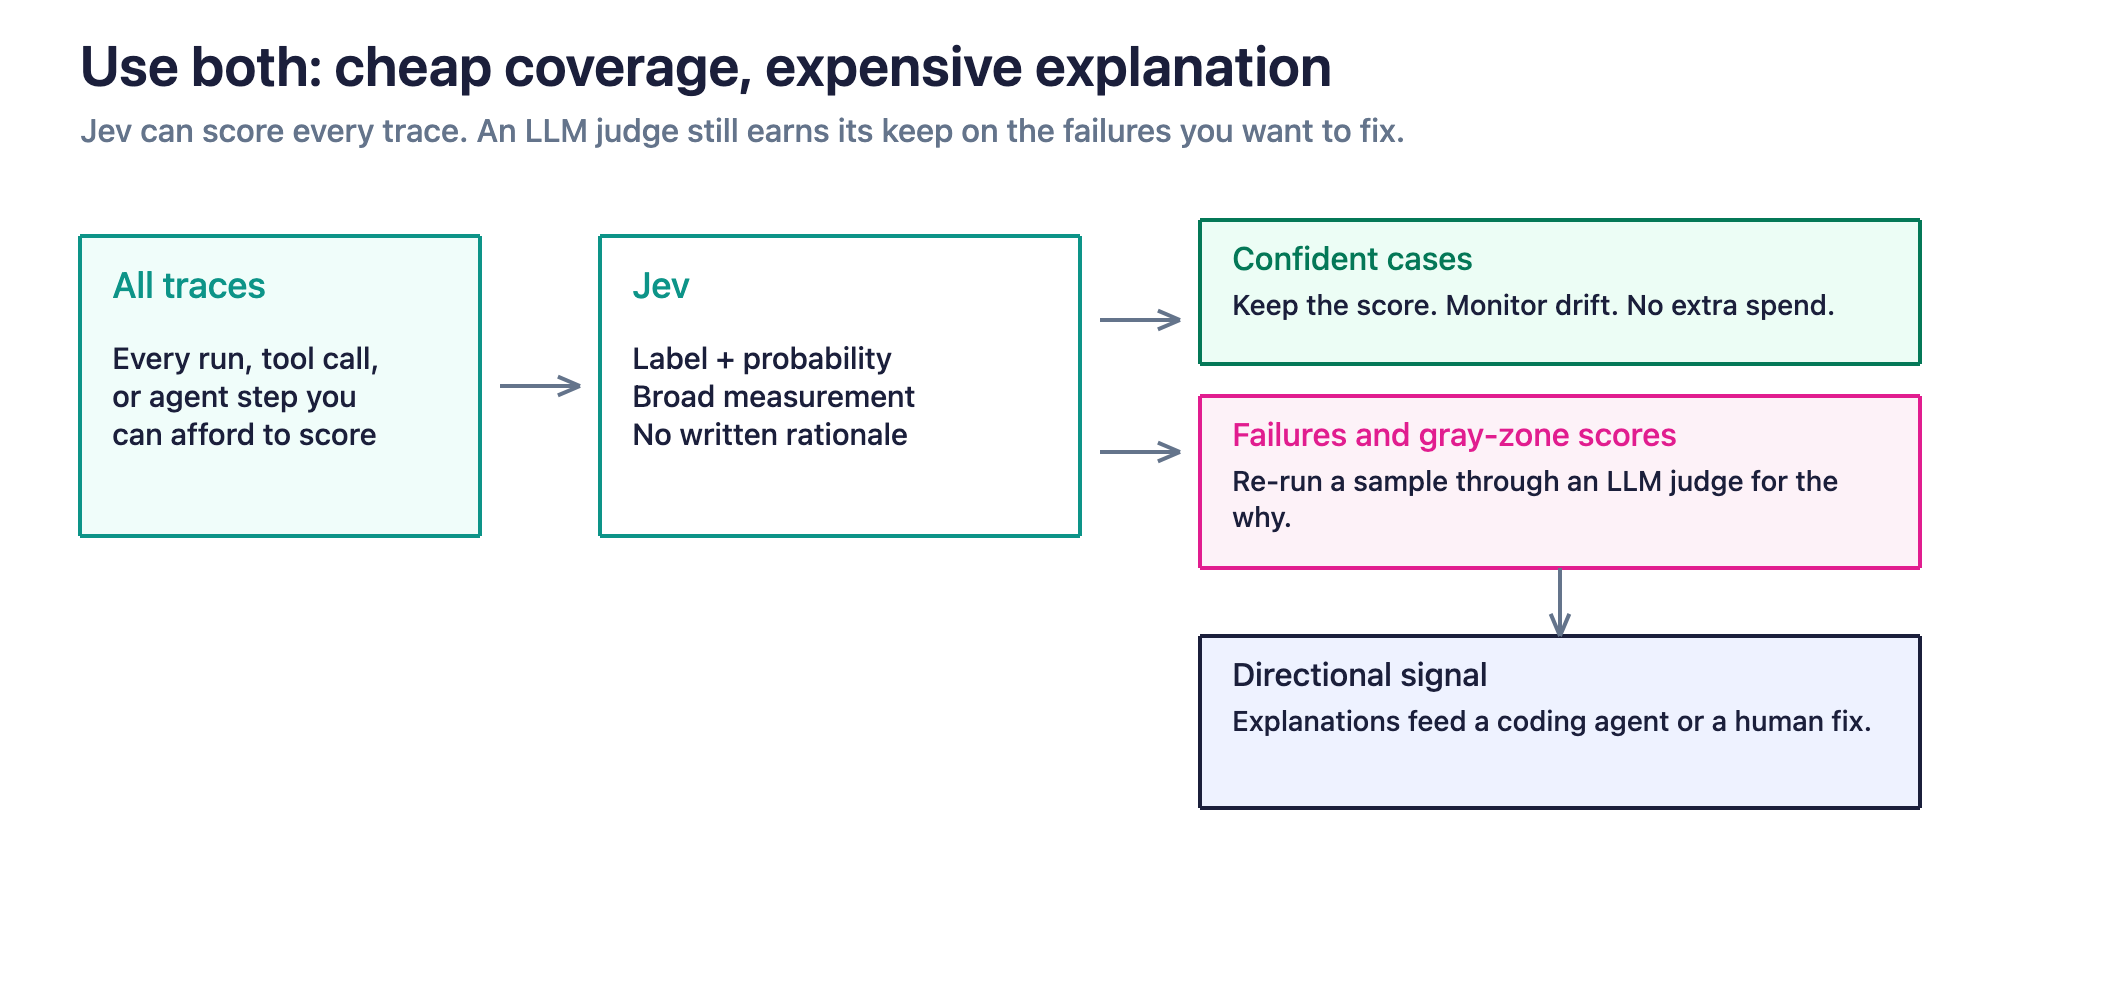
The diagram is not an argument to replace human labeling immediately. A judge can help prioritize and analyze many failures, but your initial gold set needs human-reviewed labels. Only after comparing an automated judge with this human reference set should you consider using it to scale routine review.
Complete Beginner's Course on AI Evaluations in 50 Minutes (2025) | Aman Khan
Watch Aman Khan’s explanation of manual criteria and golden-dataset construction in “Complete Beginner's Course on AI Evaluations in 50 Minutes,” published by Peter Yang. It provides a practical complement to the JSONL approach used here.
Watch manual labeling for the process of defining criteria, collecting examples, and grading them consistently. Then watch dataset sizing for a pragmatic view of starting small for internal checks and expanding before relying on the system in production. Map its spreadsheet columns to the typed fields below rather than treating a spreadsheet as the final source of truth.
5. Build a typed JSONL dataset in TypeScript
For a production repository, JSONL is a good starting format:
- each line is an independently reviewable case;
- diffs are manageable in version control;
- it streams naturally into a later evaluation runner;
- malformed rows can be isolated rather than corrupting the whole file.
Create an eval/ directory:
eval/
  intent-v1.jsonl
  validate-intent-dataset.ts
  README.md
The following Zod schema defines the authoritative shape of a gold case. It deliberately stores only the evidence intended for the Jev question; reviewer rationale is kept outside state so it cannot leak the answer into the model input.
import { z } from "zod";

const Intent = z.enum([
  "order_status",
  "return_policy",
  "technical_issue",
  "cancel_order",
  "other",
]);

const Action = z.enum([
  "route_order",
  "route_returns",
  "route_technical",
  "route_cancellation",
  "human_review",
]);

type Intent = z.infer<typeof Intent>;
type Action = z.infer<typeof Action>;

function actionFor(intent: Intent): Action {
  switch (intent) {
    case "order_status":
      return "route_order";
    case "return_policy":
      return "route_returns";
    case "technical_issue":
      return "route_technical";
    case "cancel_order":
      return "route_cancellation";
    case "other":
      return "human_review";
  }
}

export const IntentEvalCase = z
  .object({
    id: z.string().regex(/^intent-\d{4}$/),
    datasetVersion: z.literal("intent-v1"),
    split: z.enum(["development", "heldout"]),

    contract: z.object({
      questionId: z.literal("support_intent_v1"),
      questionVersion: z.literal("1"),
      policyVersion: z.literal("1"),
    }),

    state: z.object({
      message: z.string().min(1),
      conversationSummary: z.string().max(500).optional(),
      locale: z.string().optional(),
      authenticated: z.boolean(),
      channel: z.enum(["web", "email", "mobile"]),
    }),

    expected: z.object({
      intent: Intent,
      action: Action,
    }),

    review: z.object({
      outcome: z.enum(["confirmed", "corrected"]),
      reviewerCount: z.number().int().min(1),
      rationale: z.string().min(10).max(600),
    }),

    provenance: z.object({
      source: z.enum([
        "sanitized_production",
        "historical_case",
        "human_authored",
        "synthetic_gap_fill",
      ]),
      collectedAt: z.string().datetime(),
    }),
  })
  .superRefine((item, ctx) => {
    const derivedAction = actionFor(item.expected.intent);

    if (item.expected.action !== derivedAction) {
      ctx.addIssue({
        code: z.ZodIssueCode.custom,
        path: ["expected", "action"],
        message: `Expected ${derivedAction} for ${item.expected.intent}`,
      });
    }
  });

export type IntentEvalCase = z.infer<typeof IntentEvalCase>;
Here is one case in eval/intent-v1.jsonl:
{
  "id": "intent-0001",
  "datasetVersion": "intent-v1",
  "split": "heldout",
  "contract": {
    "questionId": "support_intent_v1",
    "questionVersion": "1",
    "policyVersion": "1"
  },
  "state": {
    "message": "The desktop app freezes every time I press Continue.",
    "conversationSummary": "Customer reports the issue began after updating to version 4.2.",
    "locale": "en",
    "authenticated": true,
    "channel": "web"
  },
  "expected": {
    "intent": "technical_issue",
    "action": "route_technical"
  },
  "review": {
    "outcome": "confirmed",
    "reviewerCount": 2,
    "rationale": "The request reports reproducible application behavior and does not ask about an order, return policy, or cancellation."
  },
  "provenance": {
    "source": "human_authored",
    "collectedAt": "2026-03-01T10:00:00.000Z"
  }
}
A validator can load every line and reject duplicate IDs before the dataset is committed:
import { readFileSync } from "node:fs";
import { IntentEvalCase } from "./intent-eval-case.js";

const file = readFileSync("eval/intent-v1.jsonl", "utf8").trim();

const rows = file
  .split("\n")
  .filter(Boolean)
  .map((line, index) => {
    const parsed = IntentEvalCase.safeParse(JSON.parse(line));

    if (!parsed.success) {
      throw new Error(
        `Invalid dataset row ${index + 1}: ${parsed.error.message}`,
      );
    }

    return parsed.data;
  });

const ids = new Set(rows.map((row) => row.id));

if (ids.size !== rows.length) {
  throw new Error("Duplicate evaluation-case IDs found.");
}

const heldout = rows.filter((row) => row.split === "heldout");

console.log(`Validated ${rows.length} cases; ${heldout.length} held out.`);
Two implementation details matter here:
- Keep
heldoutrows frozen. You may usedevelopmentrows while refining a question or policy, but do not repeatedly tune against the held-out cases and then call the final number unbiased. - Sanitize before storing. Replace personal names, emails, addresses, order IDs, account tokens, and raw ticket references. Preserve the structure needed for the decision, not the identifiable original record.
For example, if an order identifier only matters because its presence indicates a status inquiry, store orderIdPresent: true rather than the actual identifier. If the identifier is required for a future extraction task, that extraction task should have its own controlled dataset and privacy policy.
6. A practical first dataset checkpoint
Before expanding the dataset, make sure version one has at least:
- every supported intent represented by clear examples;
- several
otherexamples that tempt an incorrect forced route; - at least one short, noisy, and multi-intent input;
- at least one boundary case for each pair of confusable intents;
- a recorded review outcome for every gold row;
- no credentials, personal data, or evaluator notes in the model-visible state;
- a frozen held-out subset.
Do not wait for hundreds of examples to validate the mechanics. A handful of well-reviewed cases is enough to test your schema, validation script, question contract, and review workflow. Then grow the set with deliberately sampled production cases and incident-derived edge cases.
Key takeaways
A useful Jev evaluation dataset is more than prompts and expected labels. Each row should preserve:
- the minimal, sanitized state presented to the model;
- a versioned atomic decision contract;
- the expected Jev choice and its deterministic application action;
- a human review outcome that makes the label trustworthy;
- provenance and a stable split so that held-out evaluation remains meaningful.
Representative coverage includes ordinary requests, ambiguity, messy user language, and especially cases where no automated action should be taken. Those “negative” cases are what reveal a system that guesses rather than abstains safely.
Next, you will use this dataset to measure decision accuracy, automation coverage, and abstention behavior for a Jev workflow.
Can't find a good explanation? Sign up and we'll make it for you
Sign up