
Good to see you again. Last lesson established a useful boundary rule: untrusted input should become a validated Pydantic model before business logic uses it. This lesson applies that rule to persistent artifacts. AI applications continuously read prompts, configuration, evaluation cases, retrieved documents, traces, metrics, and generated outputs from files.
You will build a small, reliable file-I/O layer using pathlib for paths and with blocks for cleanup. By the end, you should be able to choose between plain text, JSON, JSONL, and CSV; read and write each format with explicit encoding; and validate records after loading them.
Paths and resource lifetime are separate concerns
A filesystem path identifies a location. An open file object is a resource your process is actively using. Keep those concepts separate:
from pathlib import Path

data_dir = Path("data")
events_path = data_dir / "generation_events.jsonl"
events_path is only a Path object. Constructing it neither creates a file nor opens one. The / operator joins path components in a platform-aware way, so it works cleanly on macOS, Linux, and Windows without manual string concatenation.
Before writing into a directory, create it deliberately:
data_dir.mkdir(parents=True, exist_ok=True)
parents=Truecreates missing parent directories.exist_ok=Truemakes repeated runs safe when the directory already exists.
For a small complete file, Path.read_text() and Path.write_text() are concise and automatically manage the open-and-close cycle:
notes_path = data_dir / "prompt_notes.txt"

notes_path.write_text(
    "Prefer concise answers with source citations.\n",
    encoding="utf-8",
)

notes = notes_path.read_text(encoding="utf-8")
write_text() overwrites an existing file. That is appropriate for a generated configuration snapshot or a fully regenerated report, but it is wrong for an append-only event log.
For appending, streaming a large file, or using CSV-specific newline behavior, open the path yourself inside a with statement:
with notes_path.open("a", encoding="utf-8") as file:
    file.write("Reject outputs that fail schema validation.\n")
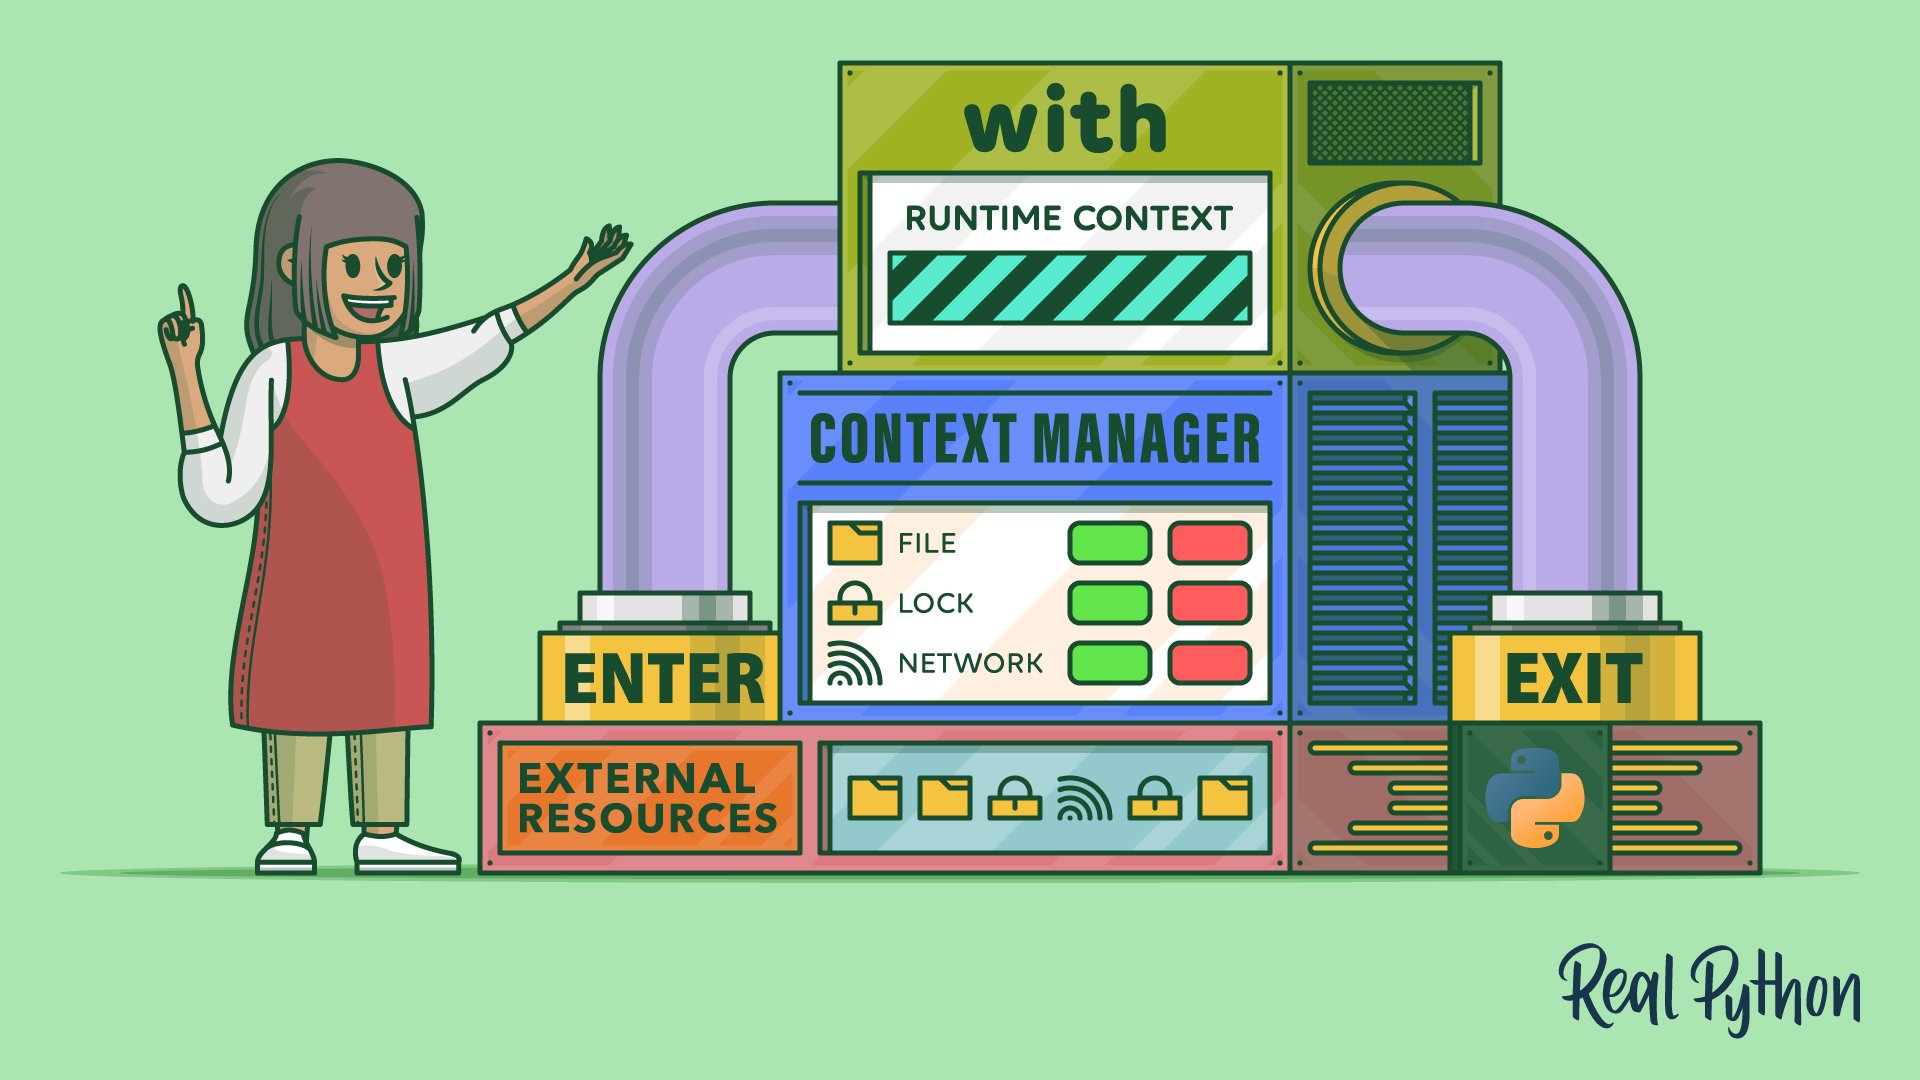
The context manager owns the resource lifetime. When the indented block ends, Python closes the file, including when an exception interrupts the code inside the block.
What Exactly are "Context Managers" in Python?
Watch “What Exactly are ‘Context Managers’ in Python?” from 2MinutesPy for the underlying lifecycle of a with block. It connects the file pattern you will use throughout this lesson to the general cleanup mechanism used for locks, connections, and other resources.
Watch the problem to see why hand-managed close() calls fail when an operation raises an exception. Then watch the lifecycle, focusing on the roles of __enter__ for setup and __exit__ for cleanup.
At this stage, you do not need to implement custom context managers. The engineering habit is simply: when you explicitly open a resource, scope it with with.
pathlib habits for application code
The standard-library pathlib.Path should generally be your default path representation rather than passing filenames around as strings.
Pathlib makes file management EASY in Python
Watch the selected parts of “Pathlib makes file management EASY in Python” by Carberra for a quick practical view of Path construction and the convenience read methods.
Watch path basics for relative paths, Path.cwd(), and platform-specific path handling. Then skip to convenience reads to see how read_text() and read_bytes() manage the open-read-close cycle for you.
A few conventions prevent common surprises:
| Need | Prefer | Reason |
|---|---|---|
| Build a child path | base / "file.json" | Cross-platform and readable |
| Ensure an output directory exists | path.mkdir(parents=True, exist_ok=True) | Safe for repeatable scripts |
| Read a small text file | path.read_text(encoding="utf-8") | Concise; closes automatically |
| Write a complete small text file | path.write_text(text, encoding="utf-8") | Concise; intentionally overwrites |
| Append or process incrementally | with path.open(...) as file: | Gives control over mode and iteration |
| Locate project files | Pass a base Path into your component | Avoids hidden dependence on the current working directory |
Avoid treating Path.cwd() as the location of your source code. It is the directory from which the process was launched, which can differ between a terminal, test runner, IDE, Docker image, and deployment environment. A function that accepts a data_dir: Path is easier to test and deploy:
from pathlib import Path


def write_run_summary(data_dir: Path, summary: str) -> Path:
    data_dir.mkdir(parents=True, exist_ok=True)

    output_path = data_dir / "run_summary.txt"
    output_path.write_text(summary, encoding="utf-8")
    return output_path
Use encoding="utf-8" explicitly for application text. It makes the contract independent of the machine’s default encoding and supports ordinary Unicode content in documents, prompts, and user-facing text.
pathlib — Object-oriented filesystem paths
Read the official Python pathlib documentation to reinforce the distinction between constructing paths and performing I/O through a path. The file-reading methods shown here are the foundation for the examples that follow.
In the “Basic use” section, review the example that imports Path, joins components using /, and opens a file. Then, in “Reading and writing files,” read from read_text() through the write_text() and write_bytes() entries. Focus on which convenience methods open and close the file automatically, and on the overwrite behavior of write_text().
Choose the format based on the shape and lifetime of data
The same Python objects can be stored in multiple formats, but the operational behavior differs significantly.
| Format | Best for | Core constraint |
|---|---|---|
| Plain text | Prompt templates, Markdown, documents, logs meant for people | Structure is your responsibility |
| JSON | One structured document: config, manifest, API fixture, complete evaluation set | Usually read and rewritten as one value |
| JSONL | Independent events, documents, requests, model outputs, evaluation cases | Each non-empty line must be valid JSON |
| CSV | Flat, tabular data: metrics exports, labels, spreadsheet exchange | Values are read as strings; nested structures need separate handling |
An AI project might use all four:
system_prompt.txtstores a prompt template.index_manifest.jsonstores one complete index metadata document.generation_events.jsonlstores one generation event per line.evaluation_metrics.csvstores results that someone may inspect in a spreadsheet.
The most important distinction is between JSON and JSONL:
- A JSON file contains one JSON value, often one object or one list.
- A JSONL file contains many independent JSON values, normally one object per line.
For a 100,000-item evaluation dataset, a JSON list requires loading or rewriting the entire list for common operations. JSONL lets you process one record at a time and append a new record without parsing the prior records.
Text and JSON: complete documents
Plain text is appropriate when the structure is primarily human-readable. For example, a prompt template may contain placeholders that your application fills later:
from pathlib import Path


def load_prompt_template(path: Path) -> str:
    return path.read_text(encoding="utf-8")


def save_prompt_template(path: Path, template: str) -> None:
    path.parent.mkdir(parents=True, exist_ok=True)
    path.write_text(template, encoding="utf-8")
read_text() is a good fit because a prompt template is normally a small, complete document.
JSON is a better fit once the content has stable nested structure. The standard-library json module translates between JSON and ordinary Python data:
import json
from pathlib import Path


def save_manifest(path: Path, manifest: dict[str, object]) -> None:
    path.parent.mkdir(parents=True, exist_ok=True)

    with path.open("w", encoding="utf-8") as file:
        json.dump(
            manifest,
            file,
            ensure_ascii=False,
            indent=2,
        )


def load_manifest(path: Path) -> dict[str, object]:
    with path.open("r", encoding="utf-8") as file:
        return json.load(file)
Example use:
manifest_path = Path("data/index_manifest.json")

manifest = {
    "schema_version": 1,
    "embedding_model": "local-embedder-v1",
    "document_count": 250,
    "chunk_size": 500,
}

save_manifest(manifest_path, manifest)
loaded_manifest = load_manifest(manifest_path)

print(loaded_manifest["embedding_model"])
# local-embedder-v1
json.dump() writes Python data to an open file, while json.load() reads from an open file and deserializes it. Setting indent=2 makes an artifact easier for humans to review in Git. Setting ensure_ascii=False preserves readable Unicode characters rather than escaping every non-ASCII character.
JSON supports:
- objects, represented by Python dictionaries;
- arrays, represented by Python lists;
- strings;
- numbers;
- booleans;
null, represented by PythonNone.
It does not directly support arbitrary Python objects such as Path, datetime, sets, or a Pydantic model instance. Convert those to JSON-compatible values first. For Pydantic models from the previous lesson, use:
json_ready: dict[str, object] = request.model_dump(mode="json")
Then pass json_ready to json.dump().
7. Input and Output — Python 3.14.0 documentation
Read the relevant official Python tutorial sections for the standard file modes, why with is the safe default, incremental file iteration, and JSON serialization.
In “7.2 Reading and Writing Files,” read the with rationale and note why a successful process exit is not a substitute for closing a file. In “7.2.1 Methods of File Objects,” read from line iteration to see the memory-efficient pattern used for JSONL. Finally, in “7.2.2 Saving structured data with json,” read the JSON introduction and compare dump() and load() with their string-oriented counterparts, dumps() and loads().
A compact mode reference:
| Mode | Meaning | Existing file behavior |
|---|---|---|
"r" | Read text | Fails if absent |
"w" | Write text | Truncates existing contents |
"a" | Append text | Preserves existing contents |
"x" | Create and write text | Fails if it already exists |
Use "x" for an artifact that should never be accidentally replaced, such as a run directory’s immutable metadata record. Use "w" only when replacing the full file is intentional.
JSONL: appendable records and streaming reads
JSON Lines, commonly called JSONL, has a simple convention: each non-empty line is standalone JSON. A file might look like this:
{"request_id":"req_001","status":"ok","latency_ms":318}
{"request_id":"req_002","status":"rejected","latency_ms":12}
{"request_id":"req_003","status":"ok","latency_ms":404}
The format is particularly useful for AI systems because a single inference or retrieval event naturally maps to one record. It is easy to append, inspect with command-line tools, process incrementally, and recover partially useful records from a long file.
Here is a minimal, typed implementation:
import json
from collections.abc import Iterable
from pathlib import Path
from typing import Any


JsonObject = dict[str, Any]


def append_jsonl(path: Path, record: JsonObject) -> None:
    """Append exactly one JSON object as one line."""
    path.parent.mkdir(parents=True, exist_ok=True)

    with path.open("a", encoding="utf-8") as file:
        json.dump(record, file, ensure_ascii=False)
        file.write("\n")


def read_jsonl(path: Path) -> Iterable[JsonObject]:
    """Yield one decoded JSON object at a time."""
    with path.open("r", encoding="utf-8") as file:
        for line_number, line in enumerate(file, start=1):
            stripped_line = line.strip()

            if not stripped_line:
                continue

            try:
                decoded = json.loads(stripped_line)
            except json.JSONDecodeError as error:
                raise ValueError(
                    f"Invalid JSON on line {line_number} of {path}"
                ) from error

            if not isinstance(decoded, dict):
                raise ValueError(
                    f"Expected JSON object on line {line_number} of {path}"
                )

            yield decoded
Use it to write individual generation traces:
events_path = Path("data/generation_events.jsonl")

append_jsonl(
    events_path,
    {
        "request_id": "req_001",
        "model": "local-llm",
        "input_tokens": 128,
        "output_tokens": 46,
        "latency_ms": 318,
        "status": "ok",
    },
)

for event in read_jsonl(events_path):
    print(event["request_id"], event["status"])
Three implementation details matter:
- Use append mode. Opening with
"a"retains earlier records. - Write the newline yourself. A JSONL record is incomplete without its line boundary.
- Iterate over the file object. This processes a large dataset one line at a time rather than calling
read()and loading the entire file into memory.
A JSONL line being syntactically valid does not make it trustworthy. Connect this to the previous lesson by validating each decoded record at the boundary:
from collections.abc import Iterable
from pathlib import Path

from pydantic import BaseModel, ConfigDict, Field


class GenerationEvent(BaseModel):
    model_config = ConfigDict(extra="forbid")

    request_id: str
    model: str
    input_tokens: int = Field(ge=0)
    output_tokens: int = Field(ge=0)
    latency_ms: float = Field(ge=0)
    status: str


def load_generation_events(path: Path) -> Iterable[GenerationEvent]:
    for raw_event in read_jsonl(path):
        yield GenerationEvent.model_validate(raw_event)
This gives you a clean division of responsibilities:
json.loads()checks JSON syntax and produces a Python object.isinstance(decoded, dict)checks the record shape at a basic level.GenerationEvent.model_validate()enforces your application’s schema.
Do not use naive JSONL appends as a substitute for a transactional message queue or database when several processes may write concurrently. It is an excellent local-development, batch-processing, and single-writer format, but concurrent durable event handling needs stronger guarantees.
CSV: interoperable tables, explicit conversion
CSV is simple and widely compatible with spreadsheets and analytics tools. It is useful for flat records such as experiment metrics:
run_id,model,accuracy,mean_latency_ms
run_001,baseline,0.81,125.4
run_002,reranked,0.86,218.7
Use Python’s csv module rather than splitting lines on commas. Quoting rules matter as soon as values can contain commas, quotes, or newlines.
import csv
from collections.abc import Iterable
from pathlib import Path
from typing import Any


METRIC_COLUMNS = [
    "run_id",
    "model",
    "accuracy",
    "mean_latency_ms",
]


def write_metrics_csv(
    path: Path,
    rows: Iterable[dict[str, Any]],
) -> None:
    path.parent.mkdir(parents=True, exist_ok=True)

    with path.open("w", encoding="utf-8", newline="") as file:
        writer = csv.DictWriter(
            file,
            fieldnames=METRIC_COLUMNS,
            extrasaction="raise",
        )
        writer.writeheader()
        writer.writerows(rows)


def read_metrics_csv(path: Path) -> list[dict[str, str]]:
    with path.open("r", encoding="utf-8", newline="") as file:
        reader = csv.DictReader(file)
        return list(reader)
The newline="" argument is intentional. It lets the csv module manage CSV newline conventions itself, avoiding platform-specific extra blank lines and preserving embedded newlines correctly.
Write a report:
metrics_path = Path("data/evaluation_metrics.csv")

write_metrics_csv(
    metrics_path,
    [
        {
            "run_id": "run_001",
            "model": "baseline",
            "accuracy": 0.81,
            "mean_latency_ms": 125.4,
        },
        {
            "run_id": "run_002",
            "model": "reranked",
            "accuracy": 0.86,
            "mean_latency_ms": 218.7,
        },
    ],
)
When you read it back, all regular CSV cells are strings:
raw_rows = read_metrics_csv(metrics_path)

print(raw_rows[0])
# {
#   'run_id': 'run_001',
#   'model': 'baseline',
#   'accuracy': '0.81',
#   'mean_latency_ms': '125.4'
# }
That is a fundamental CSV behavior, not a Python limitation. Convert types deliberately, ideally through a Pydantic model:
from pydantic import BaseModel, ConfigDict, Field


class EvaluationMetric(BaseModel):
    model_config = ConfigDict(extra="forbid")

    run_id: str
    model: str
    accuracy: float = Field(ge=0.0, le=1.0)
    mean_latency_ms: float = Field(ge=0.0)


validated_metrics = [
    EvaluationMetric.model_validate(row)
    for row in read_metrics_csv(metrics_path)
]
This catches malformed numeric values, missing columns, unexpected columns, and invalid accuracy ranges at the file boundary. In later modules, this same pattern will be useful when loading labeled evaluation sets and model-quality reports.
CSV is not suitable for nested data without an additional convention. Do not put a Python list or dictionary into one CSV cell and hope a downstream tool interprets it consistently. Prefer JSON or JSONL for records with citations, retrieved chunks, tool calls, or other nested AI data.
A practical artifact layout
A small local AI application can keep its data artifacts organized without introducing a database too early:
project/
  data/
    prompts/
      answer_system.txt
    manifests/
      corpus_manifest.json
    events/
      generation_events.jsonl
    reports/
      evaluation_metrics.csv
The file extensions communicate expected parsing, while the directory communicates the artifact’s role. A useful policy is:
- Text for authored content.
- JSON for one complete, structured snapshot.
- JSONL for independently produced records.
- CSV for flat result tables intended for review or analysis.
When you write an artifact, decide whether replacement or append is correct before selecting a method. write_text() and "w" are replacement operations; "a" is an append operation. That choice is a data-lifecycle decision, not mere syntax.
Key takeaways
Use Path objects to construct and pass filesystem locations, and use / to join path components. Create output directories explicitly with mkdir(parents=True, exist_ok=True).
For short, complete text documents, use read_text() and write_text() with encoding="utf-8". For appending, streaming, JSON, and CSV, use with path.open(...) as file: so the file closes reliably even when an exception occurs.
Choose the serialization format based on the shape of data:
- Text for unstructured human-authored content.
- JSON for one complete structured object or list.
- JSONL for appendable, independently parseable records processed incrementally.
- CSV for flat tables, with explicit type conversion after reading.
Finally, parsing is not validation. After loading JSON, JSONL, or CSV records, use the Pydantic boundary models from the previous lesson before downstream code relies on the data.
Next, you will make this I/O layer resilient by handling missing files, permission problems, malformed content, and network failures with targeted exceptions and cleanup logic.
Can't find a good explanation? Sign up and we'll make it for you
Sign up