
Hello. In the previous lesson, you practiced evaluating a C# object model in terms of encapsulation, composition, interfaces, and dependency boundaries. That same design mindset applies to collections: choose a collection for the operations and guarantees your code needs, not because “a list of things” sounds natural.
This lesson is a focused interview refresh on selecting generic collections for lookup, uniqueness, ordering, queueing, and concurrent access. The important skill is being able to defend the choice, identify a hidden requirement such as equality or concurrency, and state a sensible trade-off.
Priority: Must know. Plan for about 40 minutes, including the resource review and answering the interview prompts aloud before viewing the model answers.
Start with behavior, not class names
A collection choice begins with a few operational questions:
- Do I need to retrieve an item by position, by key, or by value membership?
- Must items be unique?
- Does “order” mean insertion order, sorted order, FIFO processing order, or LIFO processing order?
- Is the collection genuinely shared by multiple threads?
- Is the data only in memory, or does it need durability across process restarts and multiple application instances?
The first four determine the in-process collection. The fifth prevents a common senior-level mistake: treating an in-memory concurrent collection as a reliable distributed job queue or a permanent idempotency store.
Collections and Data Structures - .NET | Microsoft Learn
Read Microsoft Learn’s “Collections and Data Structures” to anchor the selection process in required operations rather than memorized class names.
In the “Choose a collection” section, read the selection table. Map each row to the question it answers: key lookup, index access, FIFO or LIFO processing, sorting, uniqueness, and safe concurrent access. Notice that the table distinguishes a general-purpose collection from its concurrent and immutable counterparts.
A good default is to use the generic collections in System.Collections.Generic. They give compile-time type safety and avoid boxing that older non-generic collections such as Hashtable can impose for value types.
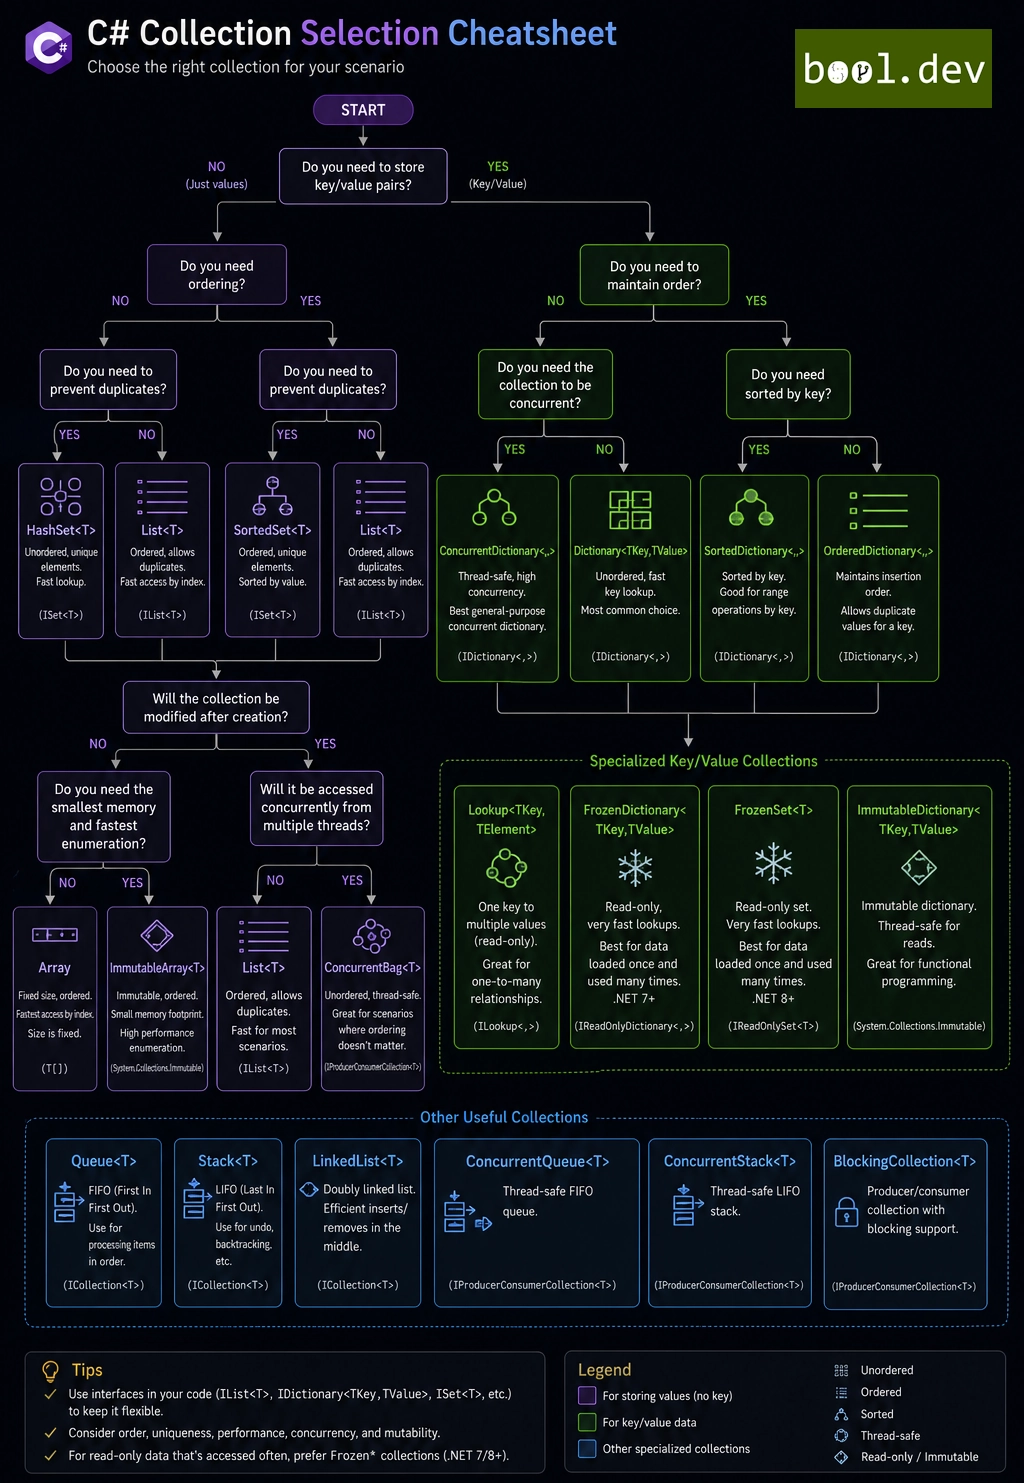
The core selection map
The table below covers the choices most likely to arise in a senior .NET interview.
| Requirement | Primary choice | Main guarantee | Important caveat |
|---|---|---|---|
| Ordered sequence, duplicates allowed, access by numeric index | List<T> | Index access is ; preserves sequence order | Contains is normally ; it does not enforce uniqueness |
| Fast retrieval of one value by a unique key | Dictionary<TKey, TValue> | Expected lookup by key | Keys must be unique; values need not be |
| Fast membership check and no duplicate values | HashSet<T> | Unique values; expected add and lookup | No meaningful sorted or positional order guarantee |
| First received item must be processed first | Queue<T> | FIFO semantics | In-memory only; not durable work delivery |
| Most recent item must be processed first | Stack<T> | LIFO semantics | Useful for undo/history and traversal, not ordinary job processing |
| Key lookup plus continuous key-sorted enumeration | SortedDictionary<TKey, TValue> | Unique keys in sorted-key order | Add and lookup are typically , not expected |
| Unique values kept in sorted order | SortedSet<T> | Uniqueness and sorted traversal | Equality is determined by comparison; comparison design matters |
| Shared dictionary across threads | ConcurrentDictionary<TKey, TValue> | Thread-safe dictionary operations | Does not make a multi-step business workflow atomic |
| Shared FIFO producer-consumer buffer | ConcurrentQueue<T> | Thread-safe FIFO enqueue/dequeue | Still not a durable queue or cross-process coordinator |
Two points often distinguish a practical answer from a memorized one:
- A
Dictionary<TKey, TValue>enforces unique keys, not unique values.dictionary[key] = valuereplaces the existing value;Addrejects a duplicate key. - A
HashSet<T>is for a set of values. ItsAddmethod reports whether a new value was actually added, which makes deduplication clear and efficient.
For example, if an import file must reject repeated external transaction IDs:
var seenTransactionIds = new HashSet<string>(
    StringComparer.OrdinalIgnoreCase);

foreach (var row in rows)
{
    if (!seenTransactionIds.Add(row.ExternalTransactionId))
    {
        throw new InvalidOperationException(
            $"Duplicate transaction ID: {row.ExternalTransactionId}");
    }
}
The case-insensitive comparer is not merely a performance choice. It declares a business rule: IDs differing only by case are considered the same. Use it only when that is truly the domain rule.
Lookup and uniqueness depend on equality
A Dictionary<TKey, TValue> and HashSet<T> are hash-based collections. Their expected performance comes from using a hash code to locate a small candidate area, then applying equality to determine whether two keys or values are actually equivalent.
This connects directly to the equality material you have already refreshed:
- If two objects are equal, they must return the same hash code.
- For a custom class used as a key or set element, implement
EqualsandGetHashCodeconsistently, typically throughIEquatable<T>. - Do not mutate fields that participate in equality or hash-code calculation while the object is inside a dictionary or set.
The last point is especially dangerous because the object may become effectively “lost” in its old hash bucket.
public sealed class PartnerKey : IEquatable<PartnerKey>
{
    public PartnerKey(string partnerCode, string region)
    {
        PartnerCode = partnerCode;
        Region = region;
    }

    public string PartnerCode { get; }
    public string Region { get; }

    public bool Equals(PartnerKey? other)
    {
        return other is not null
            && PartnerCode == other.PartnerCode
            && Region == other.Region;
    }

    public override bool Equals(object? obj)
    {
        return obj is PartnerKey other && Equals(other);
    }

    public override int GetHashCode()
    {
        return HashCode.Combine(PartnerCode, Region);
    }
}
An immutable key type is safer because the fields used for lookup cannot change after insertion. For simple domain values, a record is often a convenient choice; classes and records will be compared more fully in a later lesson.
For safe lookups where absence is a valid outcome, prefer TryGetValue:
if (partnerRules.TryGetValue(partnerId, out var rules))
{
    return rules.MaximumClaimAmount;
}

return defaultMaximumClaimAmount;
This avoids a separate ContainsKey lookup followed by an indexer access, and makes the missing-key branch explicit.
The Secret to Mastering Queue, Stack and Dictionary in C#!
Watch “The Secret to Mastering Queue, Stack and Dictionary in C#!” by Bald. Bearded. Builder. It gives a compact practical review of FIFO queue behavior and type-safe dictionary lookup.
Watch queue basics for Enqueue, Dequeue, Peek, and the FIFO processing model. Focus on why a queue is appropriate when fairness means earlier arrivals are handled first. Then watch dictionary lookup for the contrast between legacy Hashtable and generic Dictionary<TKey, TValue>, particularly TryGetValue and the importance of reliable equality and hash-code behavior for custom keys.
Interview prompt: choose collections for one workflow
Pause here and answer aloud before reading further.
An API receives a nightly reimbursement-import file. You must look up program rules by
ProgramIdfor every row, reject duplicate external transaction IDs within the file, return validation errors in the same order as the input rows, and hand accepted rows to one in-process worker in arrival order. Which collection or collections would you choose, and why?
Model answer
This workflow has several independent requirements, so I would not force them into one collection.
- I would use
Dictionary<Guid, ProgramRules>for program-rule lookup byProgramId, because the key is unique and repeated lookups are expected. - I would use
HashSet<string>for external transaction IDs because the requirement is membership and uniqueness. I would explicitly choose the appropriate string comparer based on the external ID’s case-sensitivity rules. - I would use
List<ValidationResult>to preserve the input sequence and support index-based association with the original rows. Duplicates are valid here because multiple input rows can have errors. - I would use
Queue<AcceptedRow>if one thread produces and one in-process worker consumes in FIFO order. If several threads can produce or consume from the same buffer, I would useConcurrentQueue<AcceptedRow>.
A senior-level caveat is that this queue only exists in one application process. If accepted rows must survive a restart, be retried reliably, or be consumed across scaled-out API instances, I would use durable messaging or persisted work records rather than treating ConcurrentQueue<T> as a production job system.
“Ordering” means several different things
Interview questions often use “ordered” imprecisely. Clarify the meaning before naming a collection.
A sequence in a known order
Use List<T> when the application naturally has a sequence, needs to preserve encounter order, allows duplicates, or needs index access.
A list is often the right choice for an API response, a batch of validation results, or line items on a request. Its indexed access is , but searching for a matching item with Contains, Find, or LINQ usually requires a scan of up to elements.
If you know the approximate item count, providing initial capacity can avoid repeated internal array resizing:
var results = new List<ValidationResult>(capacity: expectedRowCount);
Adding to a list is usually amortized , but resizing requires allocating a larger array and copying elements, making that individual addition more expensive.
Values continuously sorted by a business key
Use SortedDictionary<TKey, TValue> when you need both key-based access and enumeration in key-sorted order.
For example, if a report-building process continuously receives partner summaries and must enumerate them in ascending partner code without a later sort, a sorted dictionary is a reasonable fit. Its operations are generally , reflecting the cost of keeping the tree ordered.
Use SortedSet<T> when you need unique values that are also sorted. Be precise with custom comparisons: in a sorted set, two values that compare as equal are treated as duplicates, even if other fields differ.
A useful practical alternative is often simpler:
If data is collected first and sorted once for display or export, keep it in a
List<T>and callSortor use an ordered LINQ projection at the boundary. Do not pay the maintenance cost of a sorted structure unless continuous sorted access is genuinely required.
Processing order
Use a queue when items must be handled in arrival order:
var pendingApprovals = new Queue<Guid>();

pendingApprovals.Enqueue(requestId);

if (pendingApprovals.TryDequeue(out var nextRequestId))
{
    Process(nextRequestId);
}
TryDequeue is preferable when an empty queue is normal; it avoids using exceptions as control flow.
Use a stack when the newest item must come out first. Typical examples include undo history, expression parsing, and depth-first traversal. A stack is not usually appropriate for a “first request received, first request processed” business workflow.
Do not choose HashSet<T> or Dictionary<TKey, TValue> when correctness depends on a particular enumeration order. Even if a particular runtime implementation appears to enumerate in a convenient order, your code should use a collection whose documented semantics express the ordering requirement.
Thread safety: choose it only when ownership requires it
A normal List<T>, Dictionary<TKey, TValue>, Queue<T>, or HashSet<T> is not safe for simultaneous mutation by multiple threads.
However, an ASP.NET Core application handling many requests does not automatically mean every collection needs to be concurrent. A local collection created inside one request handler is owned by that request’s execution flow. It is not shared merely because other requests are running elsewhere.
A concurrent collection becomes relevant when the same instance is shared, for example:
- a process-wide in-memory cache shared by requests;
- several worker tasks consuming a common in-memory buffer;
- a singleton service maintaining shared state;
- parallel work that adds results to one common collection.
For these cases, select the concurrent collection that preserves the required semantics:
| Shared requirement | Appropriate collection |
|---|---|
| Concurrent keyed cache or lookup map | ConcurrentDictionary<TKey, TValue> |
| Multiple producers and consumers, FIFO behavior | ConcurrentQueue<T> |
| Multiple producers and consumers, LIFO behavior | ConcurrentStack<T> |
| Fast concurrent additions where order does not matter | ConcurrentBag<T> |
ConcurrentDictionary<TKey, TValue> supports useful atomic collection-level operations such as TryAdd, TryRemove, GetOrAdd, and AddOrUpdate. That does not automatically make a sequence of business operations atomic.
Consider this unsafe conceptual workflow:
- Check whether a reimbursement has already been processed.
- Charge or approve it.
- Mark it as processed.
Even if the “processed IDs” collection is a ConcurrentDictionary, a failure between steps can leave the real business state inconsistent. In a multi-instance deployment, each application process also has its own in-memory dictionary. For durable idempotency, the database or a durable message system must participate in the correctness design.
A concise interview explanation is:
I would use
ConcurrentDictionarywhen several threads in one process need safe shared keyed access. For a compound decision involving external state, I would define the atomic boundary in persistent storage or another durable coordinator; the concurrent collection alone does not provide transaction semantics.
There is a related distinction worth knowing:
- A read-only wrapper prevents consumers from mutating through that reference, but the underlying collection may still change elsewhere.
- An immutable collection does not change after creation; a modification produces a new collection instance.
Immutability can simplify safe sharing and reasoning, but it has allocation and performance trade-offs. It is not mandatory for every read-only API.
A concise senior-level answer pattern
When asked, “Why did you choose this collection?”, give an answer in this order:
-
State the required operation.
“I need repeated lookup by a unique program ID,” or “I need FIFO processing.” -
Name the collection and its useful guarantee.
“I would useDictionary<Guid, ProgramRules>for expected constant-time key lookup,” or “I would useQueue<T>because it expresses FIFO directly.” -
Name the semantic constraint.
“The dictionary key must be stable and have correct equality,” or “the set comparer must match the domain’s definition of duplicate.” -
Address scale or concurrency only if it is real.
“If the instance is shared across worker tasks, I would move toConcurrentQueue<T>.” -
State one boundary or trade-off.
“For durable processing across restarts, an in-memory concurrent queue is insufficient.”
Final interview prompt
Answer aloud in roughly 90 seconds before reading the model response.
A teammate uses
List<string>to track processed message IDs and callsContainsbefore processing each message. The service now processes a high-volume stream using several worker tasks. How would you critique the design and improve it? What further questions would you ask?
Model response
List<string> is a poor fit if the requirement is fast membership checking and uniqueness. Contains performs a linear scan, so the cost grows as the list grows. For a single-threaded in-memory process, I would use HashSet<string> with an explicit comparer that matches the message-ID contract.
Because several worker tasks now share the same tracking state, I would not use HashSet<T> without coordination. If the requirement is only safe in-process insertion of unique IDs, ConcurrentDictionary<string, byte> with TryAdd can represent an atomic “first time seen” decision.
Before implementing that, I would ask how long IDs must be retained, whether duplicate messages can arrive after a process restart, whether the service runs on multiple instances, and whether “processed” means received, successfully completed, or durably committed. If duplicate prevention must survive failures or work across instances, I would use persistent idempotency records with an appropriate unique constraint or another durable design rather than relying on application memory.
Key takeaways
- Choose collections from required operations: index, key lookup, membership, sorted traversal, FIFO, LIFO, or shared concurrent access.
- Use
List<T>for sequences and index access;Dictionary<TKey, TValue>for key lookup;HashSet<T>for uniqueness and membership checks. - Use
Queue<T>for FIFO andStack<T>for LIFO. Use sorted collections only when you need to maintain sorted access continuously. - Hash-based collections depend on stable, correct equality and hash-code behavior. A mutable key is a correctness risk.
- Use concurrent collections only when the same collection instance is actually shared among threads.
ConcurrentDictionaryandConcurrentQueueare thread-safe in-process structures, not substitutes for database transactions, durable queues, or distributed coordination.
Next, you will move from collections to delegates, lambdas, and events—how C# represents callbacks and decoupled behavior without tightly binding one component to another.
Can't find a good explanation? Sign up and we'll make it for you
Sign up